When a business reporting system is slow or inaccurate, the instinct is to look at the software. A better dashboard. A faster query engine. Or a new vendor.
In most cases, the tool is not where the failure happens.
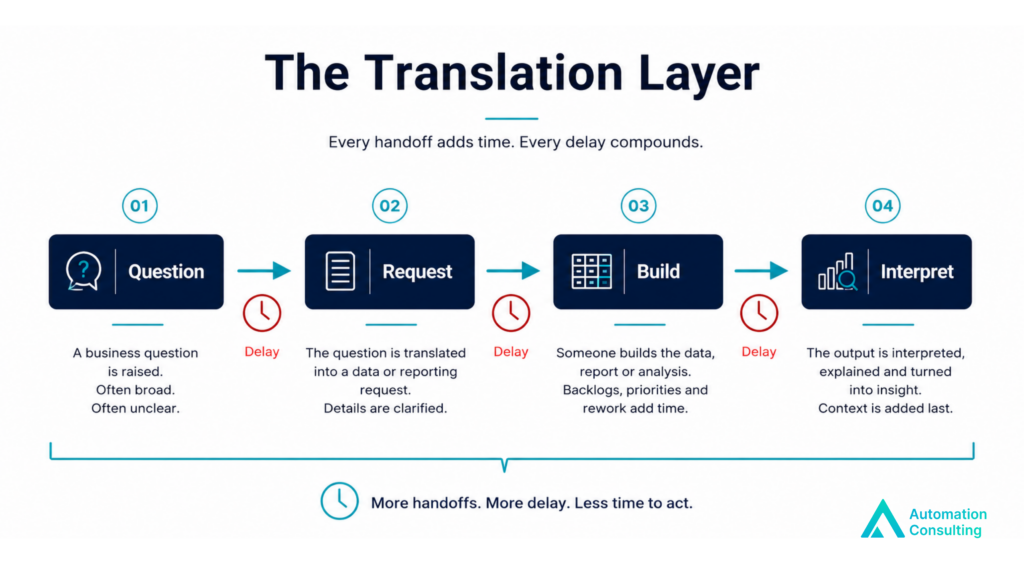
Most reporting systems require a business user to convert a question into a structured request. That request is then passed to someone with technical access. From there, a report is built and interpreted before an answer comes back. That sequence is the translation layer. Every step introduces delay. Every step is a place the original question gets distorted.
By the time an answer lands, the decision it was meant to inform may already have been made. Or the context has changed.
The Reporting Translation Layer – Automation Consulting
The four steps where business reporting breaks down
The question step
A business user has a question but cannot query the data directly. The question gets written down, described in a meeting, or sent via email. As a result, precision starts eroding immediately.
The request step
A data analyst interprets the question and translates it into a query. However, their interpretation is not always what was meant.
The build step
A report is built against the query. This takes time. In many organisations, it spans days. The business user cannot see work in progress or course-correct.
The interpretation step
Once the report lands, if the answer is unexpected, it is not clear whether the data is wrong or the assumption was. As a result, a second round of requests begins.
No faster or more expensive BI tool addresses these failure points. Only removing the translation layer does.
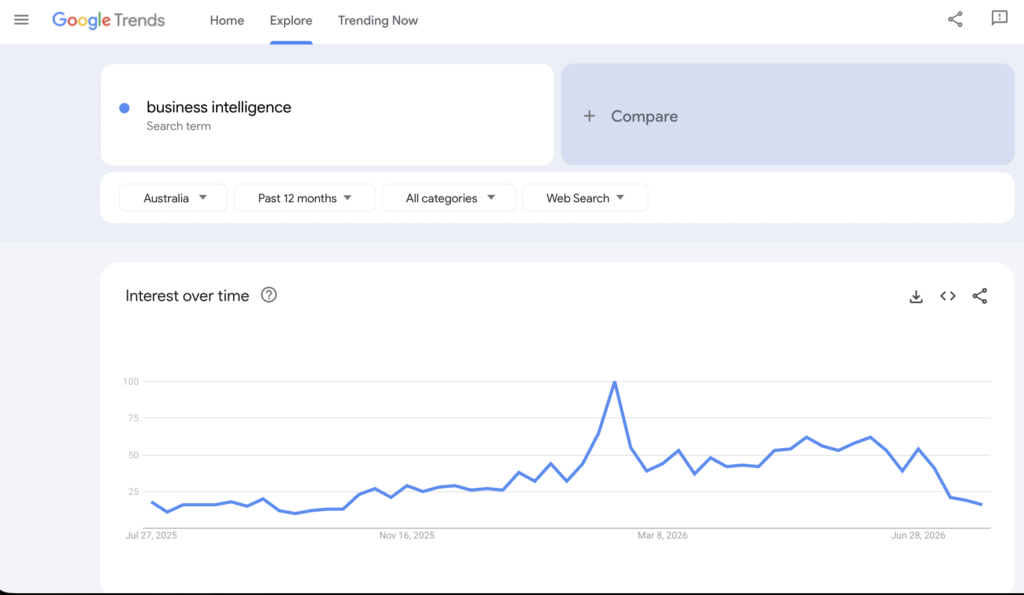
Business Intelligence Google Trends Australia 2025 2026 – Automation ConsultingBusiness Reporting Response Time Before After Agentic AI – Automation Consulting
What removing the translation layer looks like
Agentic AI applied to business reporting replaces the translation layer with direct, natural language access to data. A business user asks a question in plain English. The system queries the relevant data, runs the analysis, and returns an answer without a human intermediary at any step.
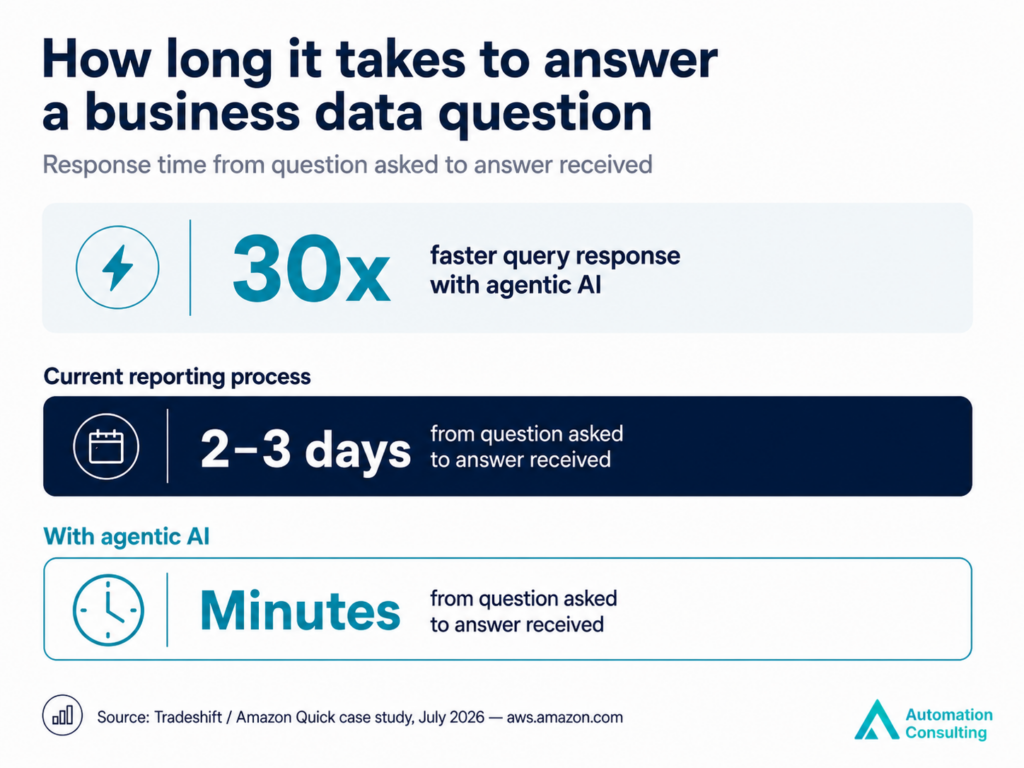
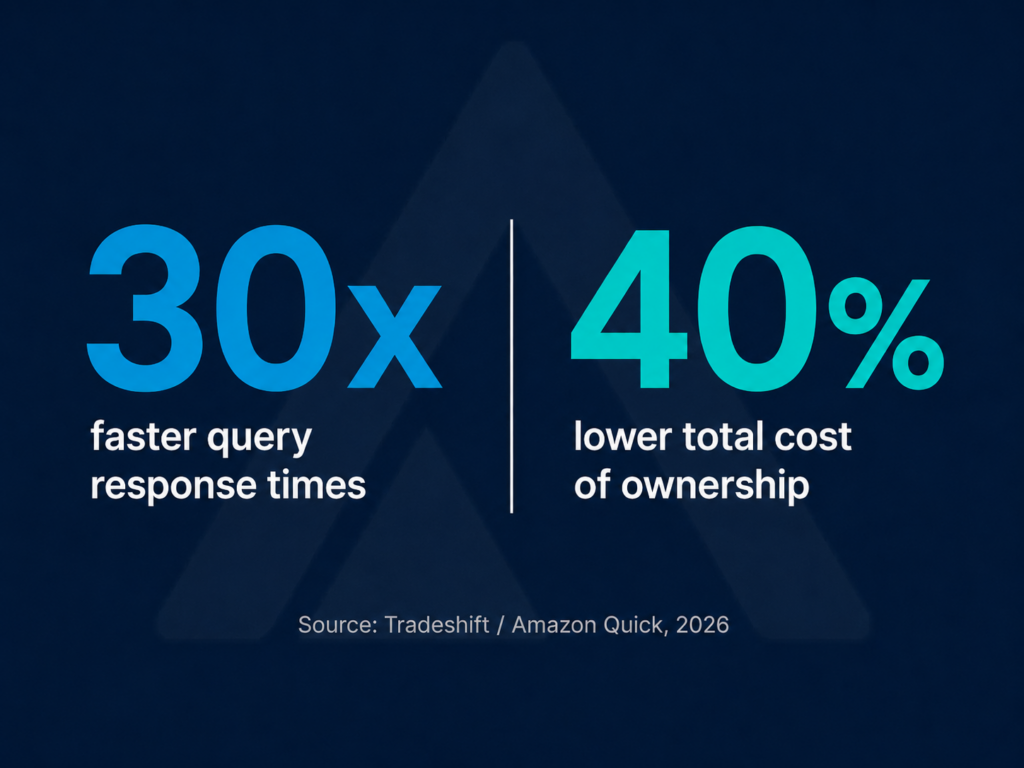
Tradeshift, an accounts payable and e-invoicing platform, replaced its in-house BI tool with an agentic AI system. Query response times improved by up to 30 times. Total cost of ownership fell by 40 per cent. Their analytics function, previously a cost centre, became a revenue-generating product.
Tradeshift Agentic AI Results 30x 40 Percent – Automation ConsultingTradeshift Amazon Quick Agentic AI Case Study – Automation Consulting
The outcome was not a better dashboard. Instead, it was the elimination of the queue. The result is real-time analytics and reporting that scales without adding analyst headcount.
What this looks like across industries
The translation layer shows up differently depending on the business, but the structural failure is the same.
Retail and ecommerce
The data questions a retail or ecommerce team asks are operational, not analytical. Sell-through rates, stock levels by location, margin by SKU, return rates on last week’s promotion. These are not questions that can wait three days. They have trade windows. A markdown call made on Tuesday about stock that should have moved on Saturday is a missed margin recovery. A reorder trigger that fires a week after sell-through data was available is a stockout. Most retail businesses are making these decisions on instinct, or on data that no longer reflects current conditions, and they have blamed their BI tool for it. The tool is not the problem.
Banking and fintech
In financial services, the cost of the translation layer is higher than elsewhere. A risk team wanting to know current portfolio exposure is not limited by its dashboard. It is limited by the time it takes a data analyst to build a query against last night’s data. A compliance team that needs a transaction anomaly report to meet a regulatory deadline is waiting on a queue, not a tool. In fintech specifically, the problem compounds: fraud patterns change, customer behaviour shifts, and a reporting stack that requires a three-day translation cycle cannot surface signals quickly enough for them to be acted on. Reporting that lands 48 hours after a question was asked is not slow. In this context, it is structurally useless.
Real estate
Property management and real estate businesses sit on significant operational data: vacancy rates, lease expiry schedules, maintenance costs by asset, rental yield by location. The problem is not a shortage of data. Rather, it is access to it. A portfolio manager wanting to know which properties have leases expiring in the next 90 days, and what comparable market rents look like, will typically wait two to three days for an answer. By the time the report lands, renewal conversations may already have started without the market rate data. The translation layer does not just slow the answer. Instead, it means the decision is made without the information that existed to support it.
Professional services
Consulting, accounting, legal, and engineering firms run on utilisation, margin, and pipeline. A principal wanting to know current utilisation across a division, or whether a specific engagement is tracking to budget, typically waits until the next weekly finance review. The resourcing decision it was meant to inform needed to be made mid-week. It arrived on Friday. The firm may have a practice management platform, a project accounting system, and a BI tool. None of those investments address the translation layer, because the layer exists in the process, not the software. However, hiring another analyst increases capacity within the layer. It does not remove it.
Across each of these industries, the pattern is the same. The fix is real-time analytics and reporting that removes the intermediary from the loop.
How to audit your own reporting stack
Before evaluating any new tooling, map one data request from the past week. Work through four questions:
Who originally asked the question? Who else had to touch it before an answer was produced? How long did it take from question to answer? Does the answer that arrived match the question that was originally asked?
If the request required more than two people or more than 24 hours, a translation layer is present. Yet changing the BI tool will not solve it. Run this as a workflow audit. It takes under ten minutes and tells you whether the problem is structural.
If you want to know what removing that layer would look like in your specific stack, that is the scope of our 20 hours free programme. We map the reporting workflow, identify where the translation layer sits, and show you exactly what removing it requires. No cost.
What is a BI translation layer?
A BI translation layer is the series of human steps required to convert a business question into a data query and back into a readable answer. In most organisations this involves at least a business user, a data analyst, and a report build step, each of which introduces latency and the risk of the original question being distorted.
How does agentic AI improve business reporting?
Agentic AI connects directly to business data and allows users to ask questions in plain language, removing the need for a human intermediary to write queries or build reports. The result is faster answers, lower overhead, and fewer errors introduced by interpretation at each handoff.
What is the difference between upgrading a BI tool and removing the translation layer?
Upgrading a BI tool addresses platform performance or interface usability. Removing the translation layer eliminates the human steps between a business question and an answer entirely. The two are not equivalent, and most BI upgrade projects do not touch the translation layer.
How do I know if my business has a translation layer problem?
Map a recent data request. If it required more than two people or more than 24 hours from question to answer, a translation layer is present. If the answer that arrived did not precisely match the question originally asked, the layer is also distorting outputs.
What does Automation Consulting do to fix business reporting problems?
We assess the reporting workflow, identify where the translation layer sits, and design an approach to remove it using workflow automation and agentic AI where appropriate. Our 20 hours free programme covers this scoping at no cost.
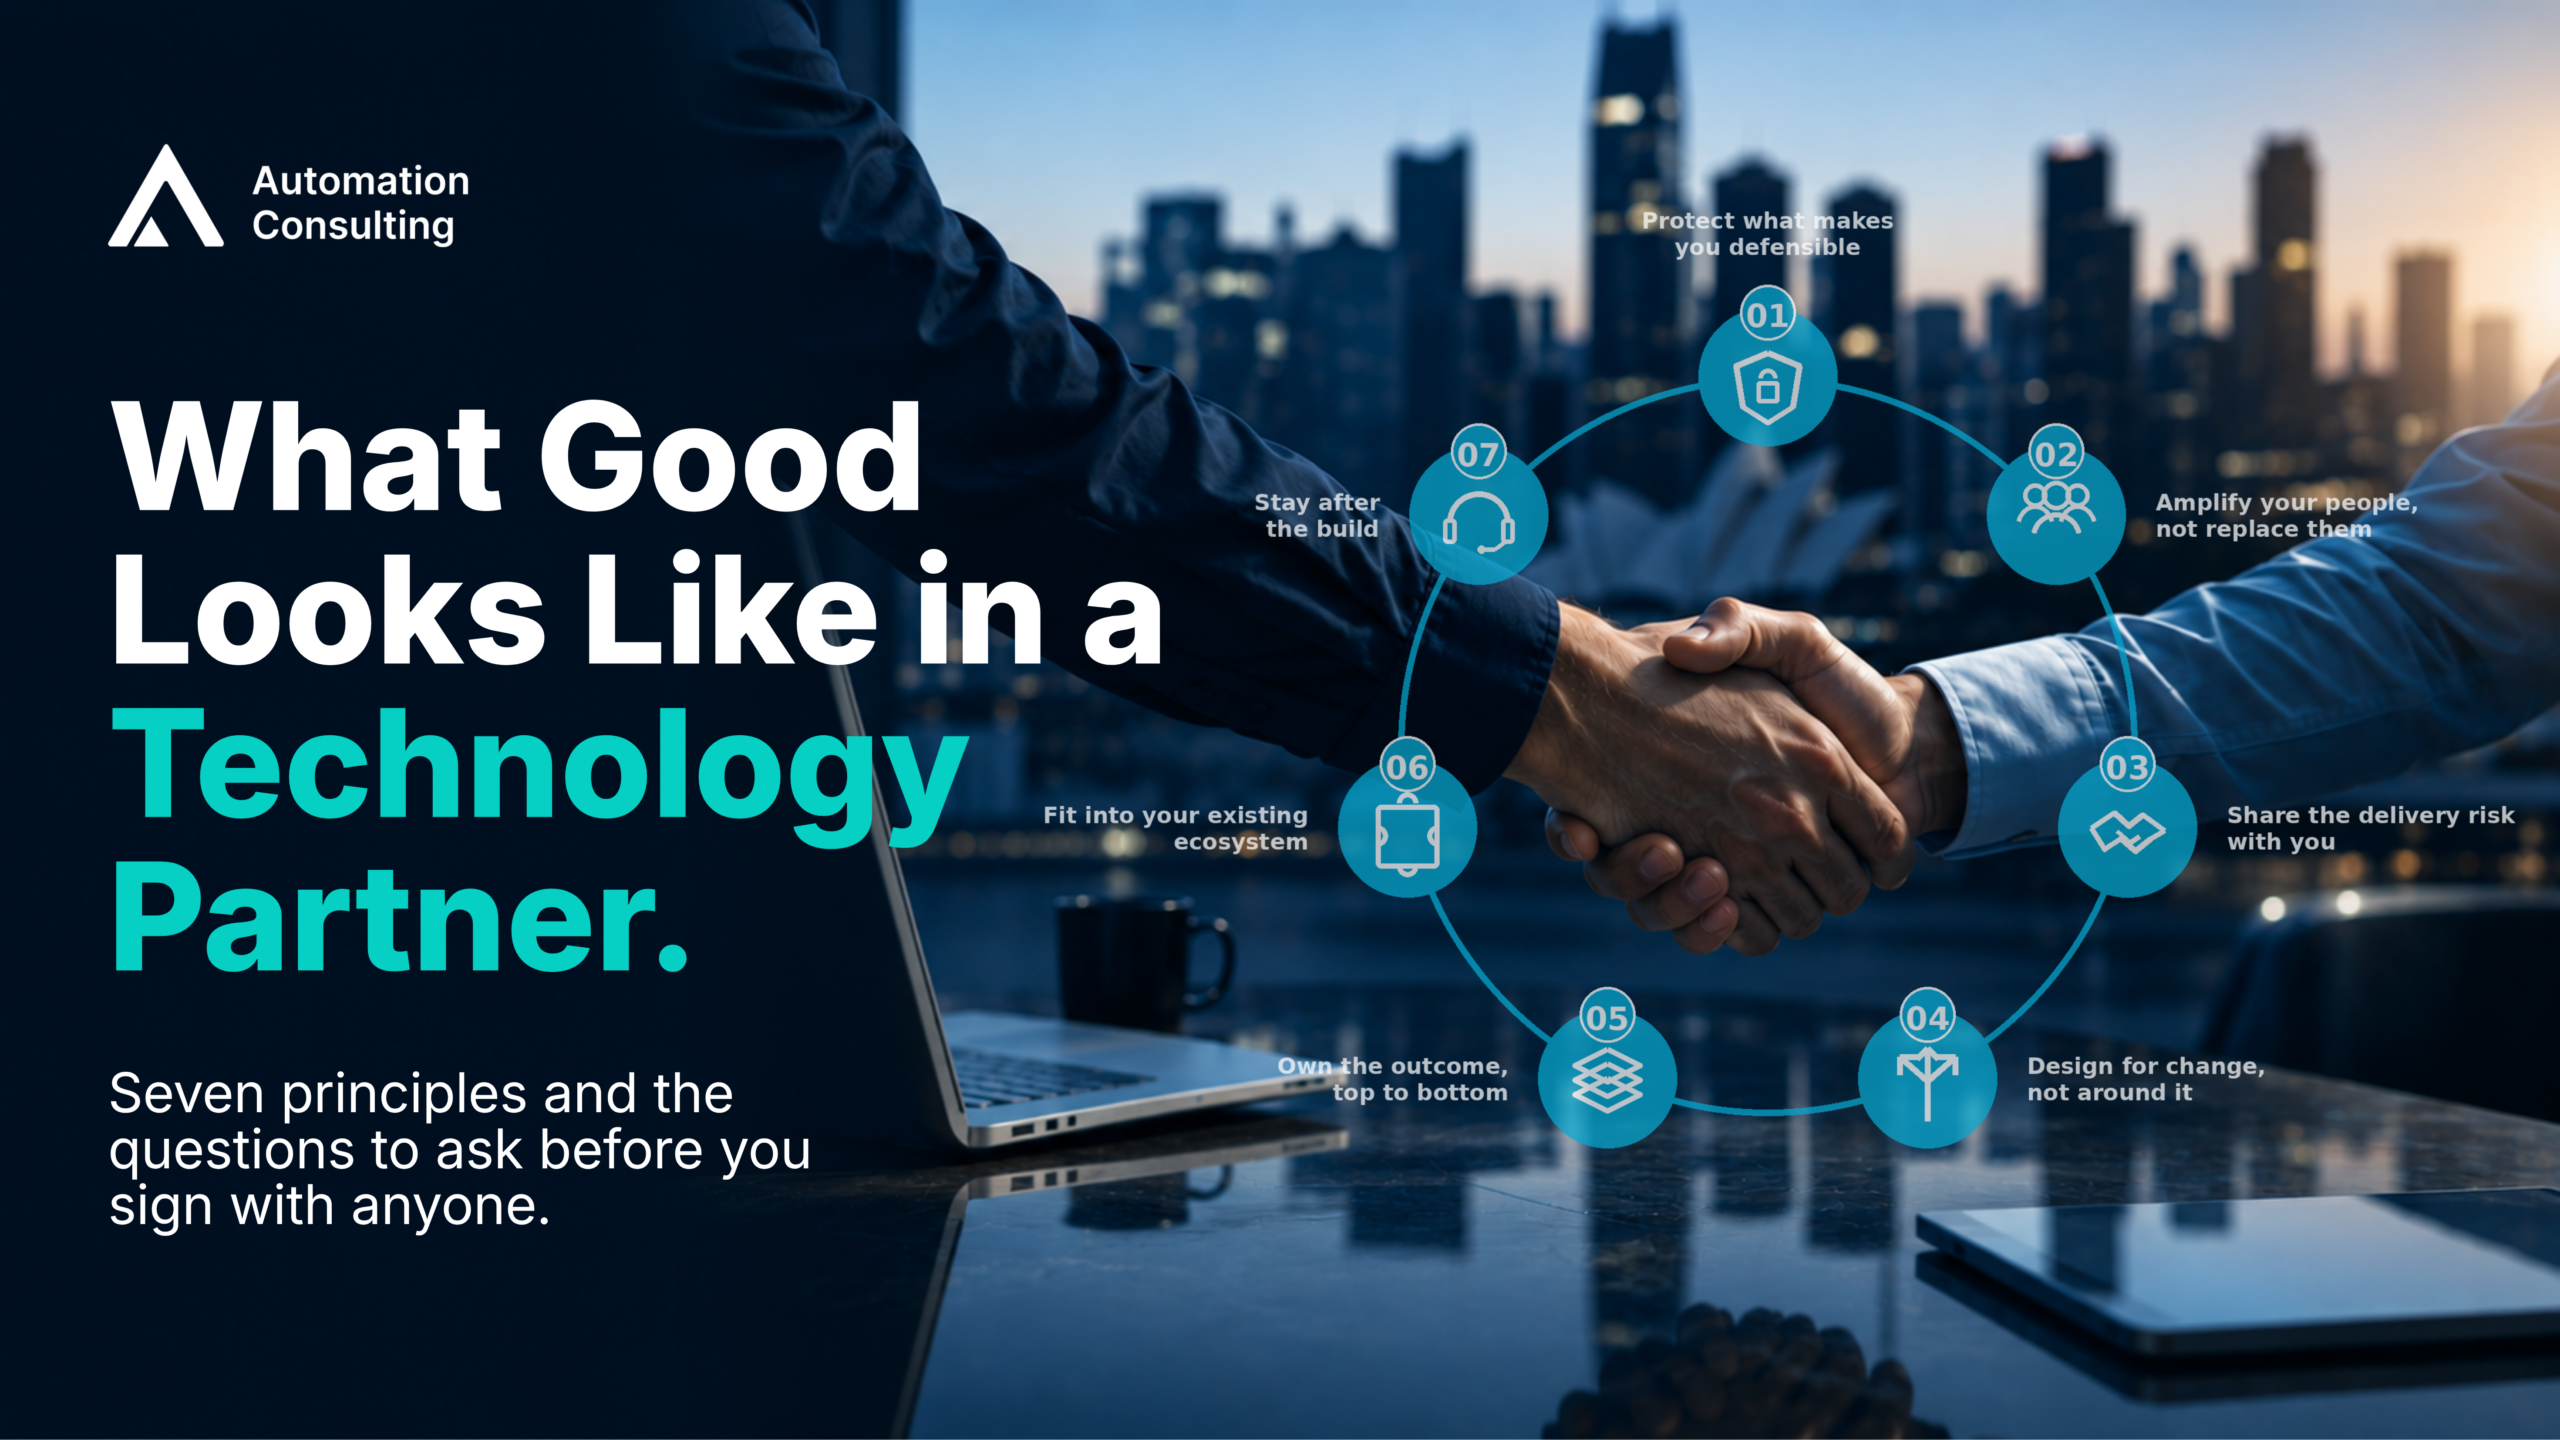
A good technology partner makes your business more capable and independent — whether you keep working with them or not. This is a practical guide to how to evaluate a technology partner: seven principles, the specific questions to ask, and the evidence to demand before you sign. Use it on any vendor before you commit.
Most technology partners look identical at the pitch stage. Every firm arrives with a polished deck, a set of impressive logos, and confident language about outcomes. The pricing structures are hard to compare. The case studies are vague. And the questions you don’t know to ask are usually the ones that matter most.
Knowing how to evaluate a technology partner for the first time is genuinely difficult. You can’t benchmark what you haven’t seen before — and most evaluation guidance either comes from the vendors themselves or treats all technology services as interchangeable. They aren’t. IP Australia’s guidance on IP ownership in contracted work is a useful starting point, but the commercial and operational risks go further than IP alone.
The framework below is what we use with clients who ask how to evaluate a technology partner — whether they’re comparing options for AI automation, workflow automation, or strategic technical oversight. We give it to them before they’ve made a choice, and we invite them to use it on us. Every principle traces back to an outcome for the business, not a feature of the vendor. Marketing decks look identical. Outcomes don’t.
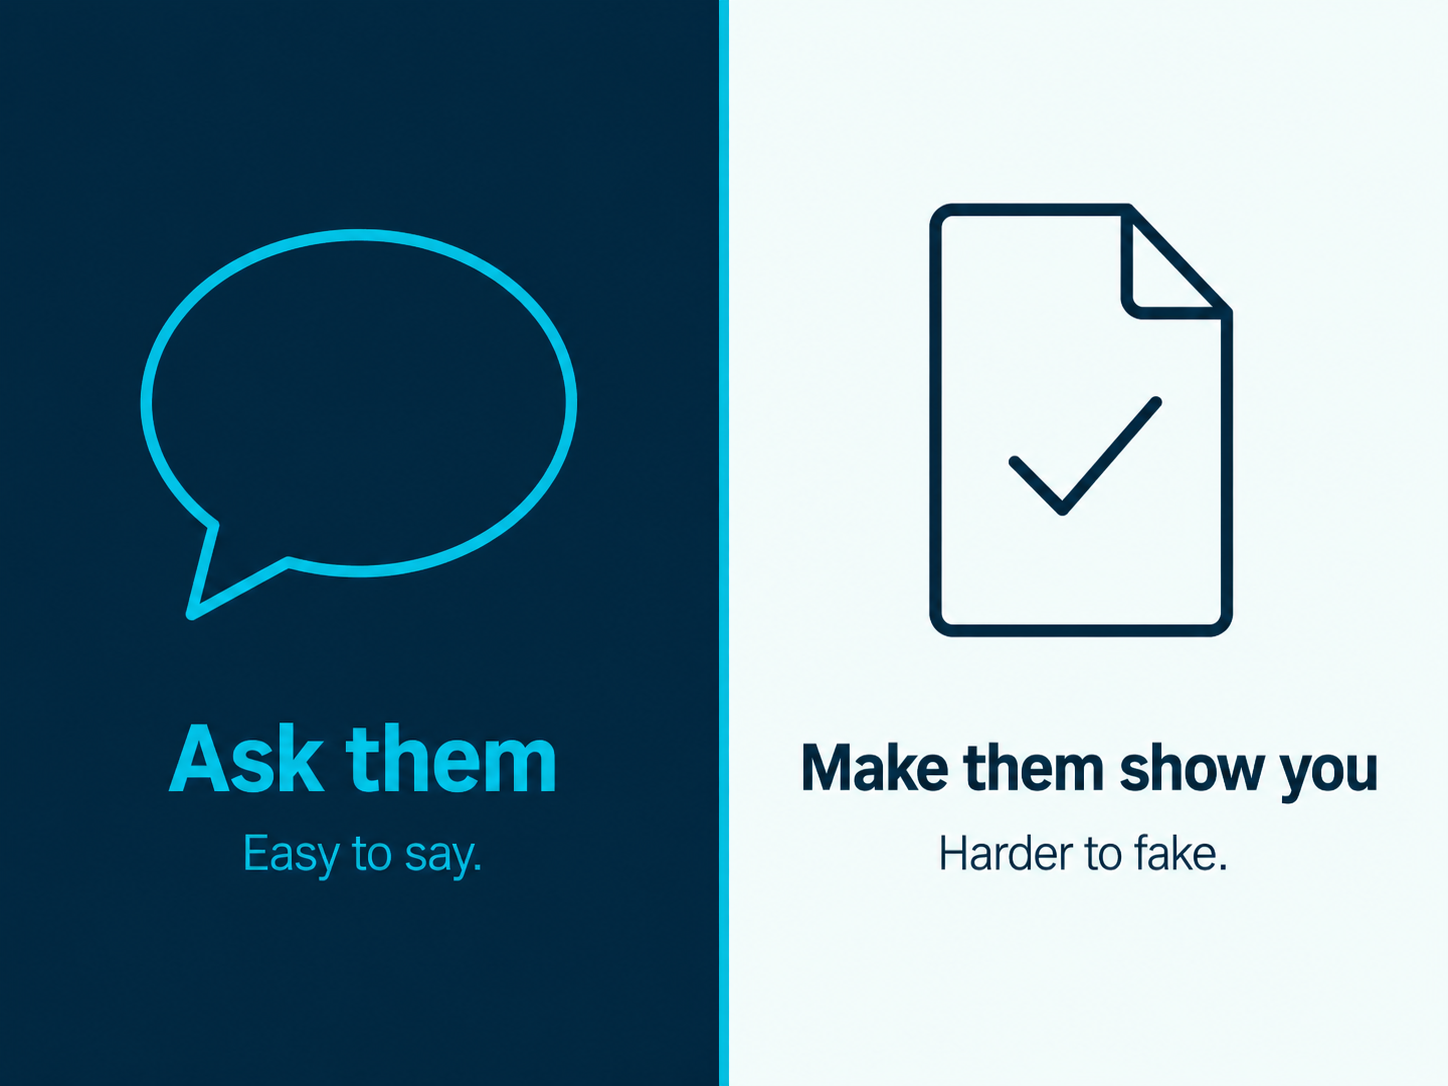
Two ways to use each principle: the Ask them question opens the conversation. The Make them show you items close it. Anyone can answer a question well in a pitch meeting. Not everyone can produce the evidence. Push every vendor from telling to showing — that’s where the differences become visible.
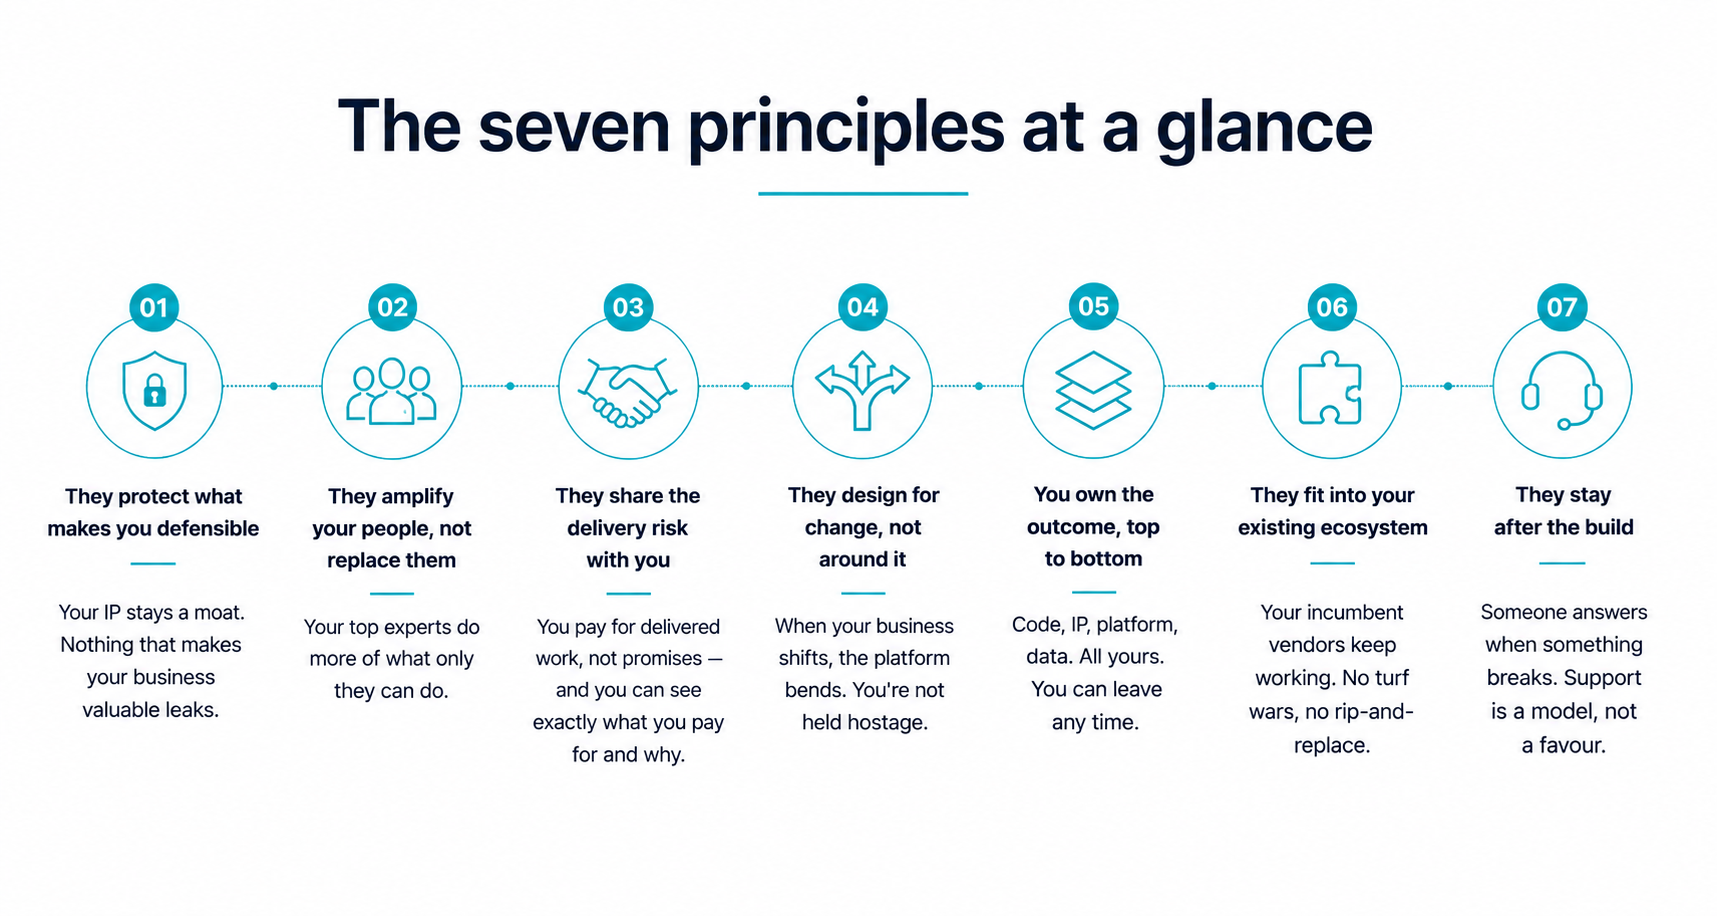
Seven principles, at a glance — each maps to a business outcome.
01. They protect what makes you defensible
The outcome you want: Your IP stays a moat. Nothing that makes your business valuable leaks, gets copied, or sits exposed on someone’s laptop.
Most technology builds accidentally erode the thing they were meant to protect. A rules engine gets ported to a browser. A calculation gets exposed through a public API. A customer-facing document reveals the logic that produces it. By the time you notice, competitors have caught up, and what once separated you is now the industry baseline.
A good partner filters every architectural decision through whether it exposes your IP. Rules engines run server-side. Customer-facing outputs are flattened, watermarked, and signed. Customers see the result, not the derivation. Access is role-based and audit-trailed by default, not bolted on after the fact.
Watch for: Vagueness about IP protection. Any suggestion that calculation logic will be exposed to a browser, a customer, or a third-party integration. “We’ll figure out security later.” No distinction between what the platform shows internally and what it shows externally.
How to Evaluate a Technology Partner: Ask Then Make Them Show You
Ask them:“Walk me through the specific architectural decision that keeps our IP from leaving the building.”
Make them show you:
A redacted architecture diagram from a previous build showing where the sensitive logic lived and how it was isolated. If they can’t produce one, they haven’t done this before.
A reference call with a client whose IP they protected. Ask that client directly: did anything leak? What did the vendor do when a design decision risked exposure?
Their standard contract clauses on IP ownership and confidentiality — before you ask for them.
02. They amplify your people, not replace them
The outcome you want: Your top experts do more of what only they can do, and less of what shouldn’t require them. The bottleneck shifts, or dissolves entirely. The people who make your business valuable stay valuable — and get to spend their time on work that actually needs them.
Most knowledge-heavy businesses hit a ceiling set by one or two people’s calendars. The tempting move is to build a platform that routes around the bottleneck — automating the expert out of the loop. That decision fails every time. The expert is still needed; you’ve just made them harder to reach.
A good partner designs for your experts as first-class users. They understand the difference between routine work (which should flow through the platform) and judgement work (which should route to the expert with everything they need to decide in minutes, not hours). They give your experts control over the rules that govern that routing.
Watch for: Any suggestion the platform will “handle approvals” or “automate expert review.” Any workflow that still requires your expert to sign off on every routine transaction, leaving the throughput cap unchanged. Any design that hides the expert’s contribution behind the platform rather than making it visible.
Ask them:“What does our expert’s day-to-day workflow look like after the platform is live? Walk me through it.”
Make them show you:
A reference call with a client’s actual expert — the person whose workflow changed, not the CEO who signed the deal. Ask the expert directly: is your day better or worse than before the platform?
A case study from a build where a key person was the bottleneck and what their role looks like now. If every case study is about headcount reduction, that tells you their philosophy.
A before-and-after workflow diagram from a real engagement showing where the expert sat in each.
03. They share the delivery risk with you
The outcome you want: You pay for delivered work, not for promises. You can see exactly what you’re paying for and why — line by line, month by month. If the vendor stops delivering, you stop paying. Neither side is locked in.
The traditional consulting commercial model transfers all delivery risk to the client. Time-and-materials with no cap. Fixed-fee that quietly becomes variable when scope shifts. Large upfront payments before value comes back. Opaque invoices where you can’t tell what you actually bought. The vendor gets paid whether or not the work is delivered on time, to spec, or to standard. That is not a partnership.
A good partner structures things so their business only works if they keep delivering. Every invoice is traceable to a specific piece of work, agreed in advance. Acceptance criteria set before the build starts, not after. Clear exit terms with modest notice periods. If the work stops delivering, either side can walk without penalty.
Watch for: Time-and-materials with no cap. Large upfront payments before delivery begins. Fixed-fee contracts where every scope discovery becomes a change-request invoice. Invoices that arrive as a single line item with a large number. Any arrangement where you cannot clearly connect a payment to a deliverable.
How to Evaluate a Technology Partner: Ask Then Make Them Show You
Ask them:“If we stopped seeing value from your delivery in month three, what would happen commercially? And can you walk me through exactly how your invoicing works — what we’d be paying for and when?”
Make them show you:
A redacted invoice from a real engagement. Can you understand it without the vendor explaining it? Line items, team allocation, what was delivered that month?
An example — a real one, with dates — of an engagement where they paused, reduced, or refunded because delivery slipped. If it’s never happened, either they’re perfect or the contract never allowed it.
Their standard exit terms in writing, before negotiation starts.
Asking the right question opens the conversation. Demanding evidence closes it.
04. They design for change, not around it
The outcome you want: When your business evolves, the platform bends. Scope changes get absorbed, not weaponised. You’re never held hostage to a mid-flight decision.
Additionally, most builds hit scope changes six weeks in. Either the vendor discovers new complexity, or you learn something you didn’t know at the start. A rigid partner turns that moment into a negotiation, and every adjustment becomes an invoice. A good partner expects it.
A good partner builds in small, self-contained units. Scope locks at each unit’s start, but honesty runs throughout. They tell you when a change is small enough to absorb and when it’s large enough to warrant a proper conversation, in writing, before anything moves. They surface complexity as soon as they see it — not after the invoice cycle.
Watch for: Any change process that turns every scope conversation into an invoice. Rigid arrangements that punish adjustment. Vague language about “we’ll re-plan” without a defined mechanism. Vendors who go quiet when complexity emerges and resurface with a change order.
How to Evaluate a Technology Partner: Ask Then Make Them Show You
Ask them:“What happens if we discover more complexity halfway through the build? Give me a specific example of how that played out with a previous client.”
Make them show you:
A change log from a real engagement showing which changes were absorbed at no charge and which were re-scoped. The ratio tells you their real philosophy.
A reference call with a client whose scope shifted materially mid-build. Ask them: how did the conversation go? Did it feel collaborative or transactional?
Their written change-management process, if one exists. No written process usually means the process is “whatever the vendor decides at the time.”
05. You own the outcome, top to bottom
The outcome you want: The code, the IP, the platform, the data. Yours. You can extend it, replace it, or take it elsewhere. You are never renting access to your own asset.
Some technology partners build platforms that only they can maintain. This arrangement makes the client technically the owner but practically the tenant. Six months in, extending the platform means going back to the same vendor, at the same rate, without any alternative.
A good partner delivers full source code ownership from the start. A shared repository with your team credentialled from day one. Documentation produced as a work artefact, not an afterthought. Another partner could pick up the codebase within a week if you needed them to.
Watch for: Any licencing arrangement where you rent access to your own platform. Code that lives only on the vendor’s infrastructure. Exit terms that make leaving expensive, slow, or contingent on the vendor’s cooperation.
How to Evaluate a Technology Partner: Ask Then Make Them Show You
Ask them:“If we ended the engagement tomorrow, what could we take with us and what would stay?”
Make them show you:
The repository access structure from a current engagement (redacted). Who has access? Is the client’s team credentialled, or is access “available on request”?
A sample of their documentation from a previous build. Could a new developer, with no contact with the vendor, understand it?
The strongest proof there is: a reference call with a client who left them and took the platform to another partner — and whether the vendor gave that reference willingly.
06. They fit into your existing ecosystem
The outcome you want: The vendors, tools, and partners you already trust keep working. The new platform doesn’t ignite turf wars with your incumbents. Your business runs while the platform is being built, not in spite of it.
Moreover, very few technology decisions happen in isolation. Most businesses already have an ERP, a CRM, an incumbent development partner, existing licences and contracts. A partner that ignores that ecosystem isn’t proposing a technology solution — they’re proposing a disruption.
Additionally, a good partner maps your existing ecosystem during discovery. They define the integration boundary with your incumbents in writing before the build starts. Where their scope overlaps with someone else’s, they clarify who owns what — and put it in the contract.
Watch for: Any suggestion that your existing vendors need to be replaced. Vagueness about integration boundaries. “We’ll take over that work.” Refusal to engage directly with your incumbents. Any pattern of the vendor complaining about an incumbent to you rather than solving it with them directly.
Ask them:“How do you plan to coordinate with our existing vendors during this build?”
Make them show you:
The name of an incumbent vendor they’ve worked alongside on a previous engagement — then call that vendor, not just the client. The incumbent’s view of them is the least-varnished reference you’ll get.
A written integration boundary document from a previous build. If they’ve never produced one, the boundaries were never defined.
An example of a scope overlap with an incumbent and how it was resolved — specifics, not principles.
07. They stay after the build
The outcome you want: Someone answers when something breaks. Support is a model with names, response times, and a price — not a favour you have to negotiate at 5pm on a Friday. The team that built your platform doesn’t vanish the day it goes live.
Furthermore, most consultancies specialise in the build phase only. The engagement ends, the team rolls onto the next client, and six months later — when something breaks, or a browser update kills a feature, or you need one small addition — you are starting a new commercial conversation with no guaranteed outcome.
When you evaluate a technology partner, one of the clearest signals is what their post-build model looks like. A good partner puts this in the proposal, not in a follow-up conversation. Named support contacts, defined response times for different severities, a clear price for ongoing support versus warranty — in writing, before you sign.
Watch for: No mention of what happens after go-live. Support “available on request” with no defined model. Warranty terms that are vague or absent. Any vendor whose proposal ends at the launch date. A support price that only appears after you’ve signed the build contract.
Ask them:“It’s six months after go-live and something breaks on a Friday afternoon. Who do I call, what happens next, and what does it cost?”
Make them show you:
Their standard support agreement — response times, severity definitions, pricing — before you sign the build contract, not after.
A reference call with a client who is 12 or more months post-launch. Ask them: what happened the last time something broke? How long did it take? What did it cost?
The name of the person who would own your account after go-live. If the answer is “we’ll assign someone,” the model doesn’t exist yet.
How to Evaluate a Technology Partner Using This Framework
To get the most from this guide on how to evaluate a technology partner, take the “ask them” question from each principle and sit down with every vendor you’re considering. Ask the same questions, in the same order. Do not fill in silences. Do not accept marketing generalities in place of specific answers.
Then push past the answers. Every principle carries a “make them show you” list — references you can actually call, artefacts they can actually produce, clients who were in your position 12 or 18 months ago. Anyone can answer a question well in a pitch meeting. The evidence is where vendors separate.
Two questions worth asking every vendor, regardless of principle:
“Can you show me a client who is no longer working with you, and would they take a call from me?”
“What would you build differently if you knew from day one that we might not renew?”
In practice, the differences in how partners respond to these questions will be diagnostic. Any partner who is uncomfortable with them is telling you something about what the rest of the engagement will feel like.
You are welcome to use this framework on us.
If a partner hesitates to be evaluated against it, that hesitation is itself an answer.
The one-sentence version
Every principle in this guide to how to evaluate a technology partner is a version of the same question.
Does this partner make your business better off, whether you keep working with them or not?
Typically, the vendors who fail this test optimise for lock-in: of your IP, your capital, your expertise, your ecosystem. Every commercial and architectural decision is quietly designed to make leaving harder. However, the vendors who pass it optimise for your leverage. You should end the engagement stronger, more capable, and freer than you started.
If they have done their job well, you should have more options at the end, not fewer.
Specific Questions Worth Answering Before You Sign
How to evaluate AI consulting partners for ecosystem fit
Ecosystem fit means the partner can work within your existing stack without requiring you to replace it. The test is not whether they know your tools — it is whether they ask about them before proposing anything.
Ask them to name the tools your business already uses. Ask how their solution will connect to them. Ask what the integration boundary looks like and who maintains it after go-live. A partner with genuine ecosystem experience will answer in specifics: which APIs, which middleware, which authentication approach. A partner without it will describe the capability in general terms and defer the detail to later.
The third test: ask what happens if you need to add a new tool in 12 months. If the answer requires their ongoing involvement, that is a dependency, not a solution.
What a CTO should prioritise when evaluating AI partnership options
In order: IP ownership, documentation quality, skills transfer, and exit terms.
IP ownership determines whether the models, prompts, training data, and workflows built during the engagement belong to your business or the vendor. If the vendor retains ownership of the AI logic they build for you, you cannot move, modify, or rebuild it without them.
Documentation quality determines whether your team can understand, maintain, and extend what was built. Ask for a sample handover document from a previous project. If it is thin or relies on tribal knowledge, plan accordingly.
Skills transfer determines whether your technical team grows from the engagement or becomes more dependent on the vendor. The right partner runs sessions with your developers, not just presentations to your leadership. Exit terms determine the cost of switching. If the commercial structure makes leaving expensive, factor that into the risk assessment before you sign.
How to evaluate discovery workshop capability in a software or AI partner
The output of a discovery workshop should be a scope document your team can read without the vendor in the room. If it requires interpretation, it is not finished.
Good discovery capability shows up in four ways. First, the workshop runs to a structured agenda with named outputs, not an open conversation. Second, the partner captures requirements in your language, not theirs. Third, the scope document distinguishes between what is fixed, what is flexible, and what is out of scope. Fourth, there is a change control process explained before the build starts, not negotiated after the first change request lands.
Ask to see a sample statement of work or scope document from a previous engagement. Ask who runs the discovery — a consultant or a developer. Ask what happens to requirements that emerge mid-project.
What a typical automation engagement looks like: discovery, build, testing, and handover
A well-run automation engagement has four distinct phases, each with a clear output before the next begins.
Discovery runs for one to three weeks. The output is a documented process map, a list of automation candidates ranked by effort and business impact, and a scope with acceptance criteria written before the build starts. If acceptance criteria come after the build, there is no agreed definition of done.
Build is iterative with client checkpoints, typically every one to two weeks. You should see working software at each checkpoint, not status updates. Testing uses the acceptance criteria from discovery. Your team runs user acceptance testing, not just the vendor’s QA. Any issue raised during testing maps to a specific criterion from the scope.
Handover includes working code in your repository, documentation your team can follow, a training session for the people who will use or maintain the system, and a defined support window. A handover that consists of a video call and a shared folder is not a handover.
How to protect your business IP and data when working with an AI or automation consultant
The contract governs this. Read the IP assignment clause before you sign anything.
The specific questions to ask: who owns the models, prompts, training data, and workflows built during the engagement? Where is your data stored and processed? What happens to your data if the engagement ends? Is there a data deletion clause?
The practical test: ask the vendor what you would take with you if the engagement ended tomorrow. The answer should be everything built for you, stored in your systems, with no ongoing dependency on theirs. If the answer is conditional or unclear, that is your answer.
Red flags to look for when scoping an AI automation project with a new partner
They cannot give a fixed price or estimate without a paid discovery, but the discovery scope itself is also undefined. One paid discovery is reasonable. An undefined chain of them is not.
The proposal is written in capability language rather than outcome language. Features and platform descriptions are not a scope. Outcomes, acceptance criteria, and timelines are.
They do not ask about your existing systems or team capability in the first conversation. References they offer are from their own network, not from clients in a situation similar to yours. Exit terms are absent from the proposal. IP ownership is deferred to legal review without a stated intent in the commercial terms.
What makes a good technology partner?
This guide to how to evaluate a technology partner comes down to one test: does this partner make your business better off whether you keep working with them or not? That means they protect your IP ownership, document everything thoroughly, build your team’s capability rather than their own dependency, and structure contracts with exit terms that don’t penalise you for leaving.
What questions should I ask when evaluating a technology vendor?
The most diagnostic questions aren’t about features. Ask to speak with a client who is no longer working with them. Ask them to show you a post-mortem from a project that didn’t go to plan. Ask what they would build differently if they knew from day one you might not renew. Partners who answer these questions comfortably are telling you something about how the engagement will feel.
How do I avoid vendor lock-in with a technology partner?
The warning signs are: IP ownership held by the vendor, documentation that lives in their systems rather than yours, skills that only exist in their team, and commercial terms that make switching expensive. A genuine partner writes code you own, documents in your systems, and trains your people so that leaving is a business decision, not a technical crisis.
How do I evaluate an AI automation or workflow automation partner?
Beyond the standard questions, look for partners who can show completed projects with documented business outcomes rather than demos. Ask who owns the models, prompts, and pipelines they build for you. Ensure they can explain the solution to your operations team, not just your technical lead, and that handover documentation is included in the delivery scope.
What is the difference between “ask them” and “make them show you” in vendor evaluation?
Ask them questions open the conversation — any vendor can answer a question well in a pitch. Make them show you means demanding specific evidence: references you can call, documentation you can read, and clients who were in your position 12 months ago and will take a call. The gap between what vendors say and what they can produce is where the real differences become visible.
How do we evaluate AI consulting partners for ecosystem fit?
Ecosystem fit means the partner can work within your existing stack without requiring you to replace it. Ask them to name the tools your business already uses and explain how their solution connects to them. A partner with genuine ecosystem experience answers in specifics: which APIs, which middleware, which authentication approach. Also ask what happens if you need to add a new tool in 12 months. If the answer requires their ongoing involvement, that is a dependency, not a solution.
What should a CTO prioritise when evaluating AI partnership options?
In order: IP ownership, documentation quality, skills transfer, and exit terms. IP ownership determines whether the models, prompts, and workflows built belong to your business or the vendor. Documentation quality determines whether your team can maintain what was built. Skills transfer determines whether your developers grow from the engagement. Exit terms determine the real cost of switching. Ask for a sample handover document from a previous project before signing anything.
How do I evaluate discovery workshop capability in a software or AI partner?
The output of a discovery workshop should be a scope document your team can read without the vendor in the room. Good discovery capability shows up four ways: a structured agenda with named outputs, requirements captured in your language, a scope that distinguishes fixed from flexible from out of scope, and a change control process explained before the build starts. Ask to see a sample statement of work from a previous engagement.
What does a typical automation engagement look like across discovery, build, testing, and handover?
Discovery runs one to three weeks and produces a process map, ranked automation candidates, and acceptance criteria written before the build starts. Build is iterative with client checkpoints every one to two weeks — you should see working software at each checkpoint, not status updates. Testing uses the acceptance criteria from discovery, run by your team. Handover includes working code in your repository, documentation your team can follow, a training session, and a defined support window.
How do I protect my business IP and data when working with an AI or automation consultant?
The contract governs this — read the IP assignment clause before you sign. Ask specifically: who owns the models, prompts, training data, and workflows built during the engagement? Where is your data stored? What happens to your data if the engagement ends? The practical test: ask the vendor what you would take with you if the engagement ended tomorrow. The answer should be everything built for you, in your systems, with no ongoing dependency on theirs.
What red flags should I look for when scoping an AI automation project with a new partner?
Six signals worth taking seriously: they cannot give a fixed estimate without a paid discovery but the discovery scope is also undefined; the proposal uses capability language rather than outcome language; they do not ask about your existing systems in the first conversation; references come from their own network rather than clients in a similar situation; exit terms are absent from the proposal; IP ownership is deferred to legal review without a stated position in the commercial terms.
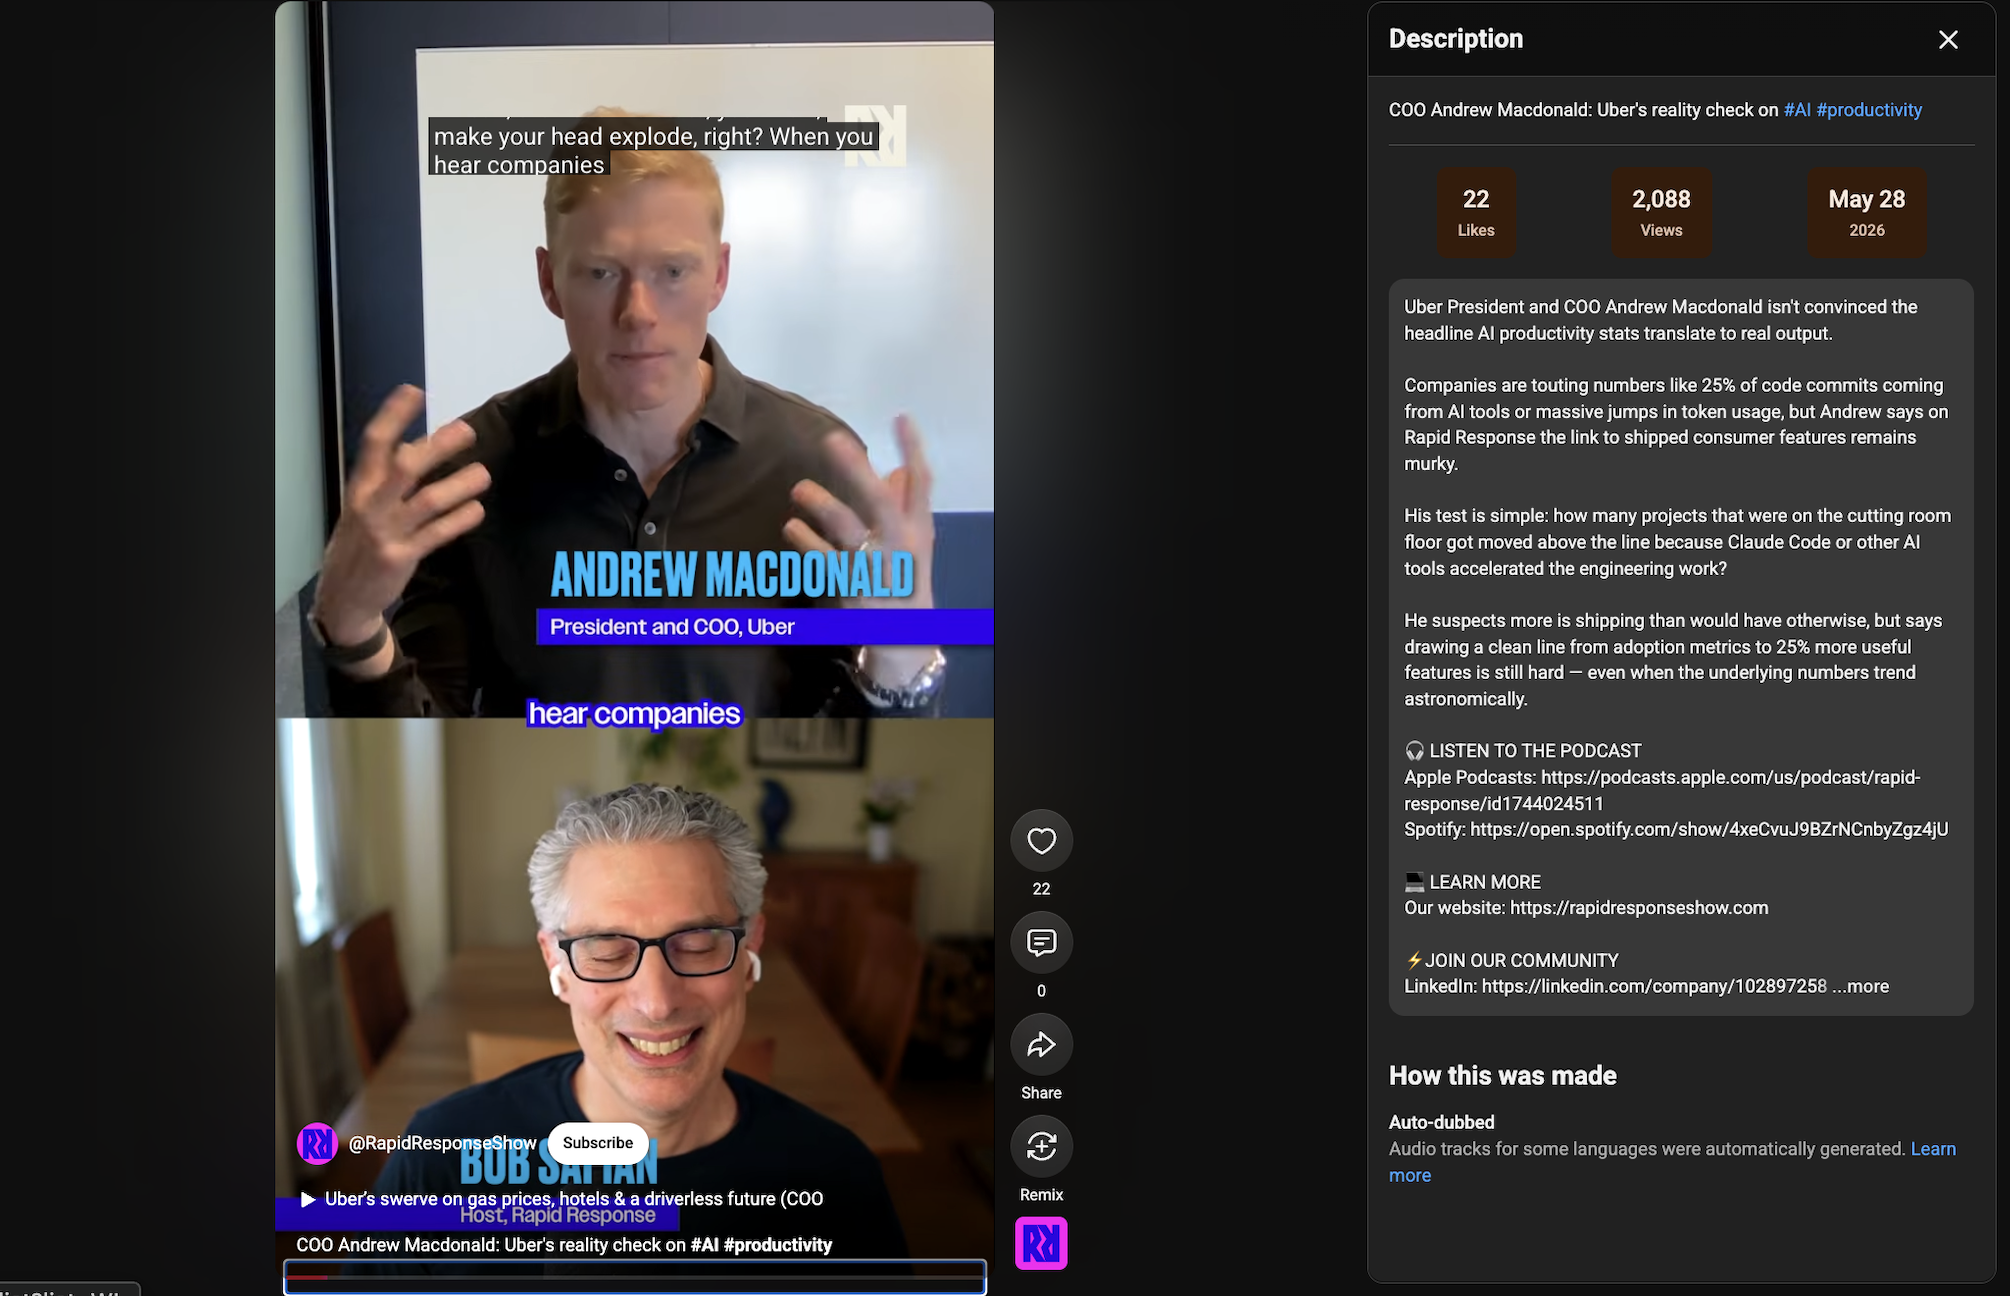
If you are trying to work out how to measure AI ROI, Uber’s COO Andrew Macdonald gave the clearest answer by accident, in a May 2026 Rapid Response interview that most companies are quietly living but nobody says out loud. The business had burned through its entire AI coding budget in four months. His conclusion: higher token usage did not translate into a proportional increase in useful consumer features. The link between spend and value, he said, was genuinely hard to draw.
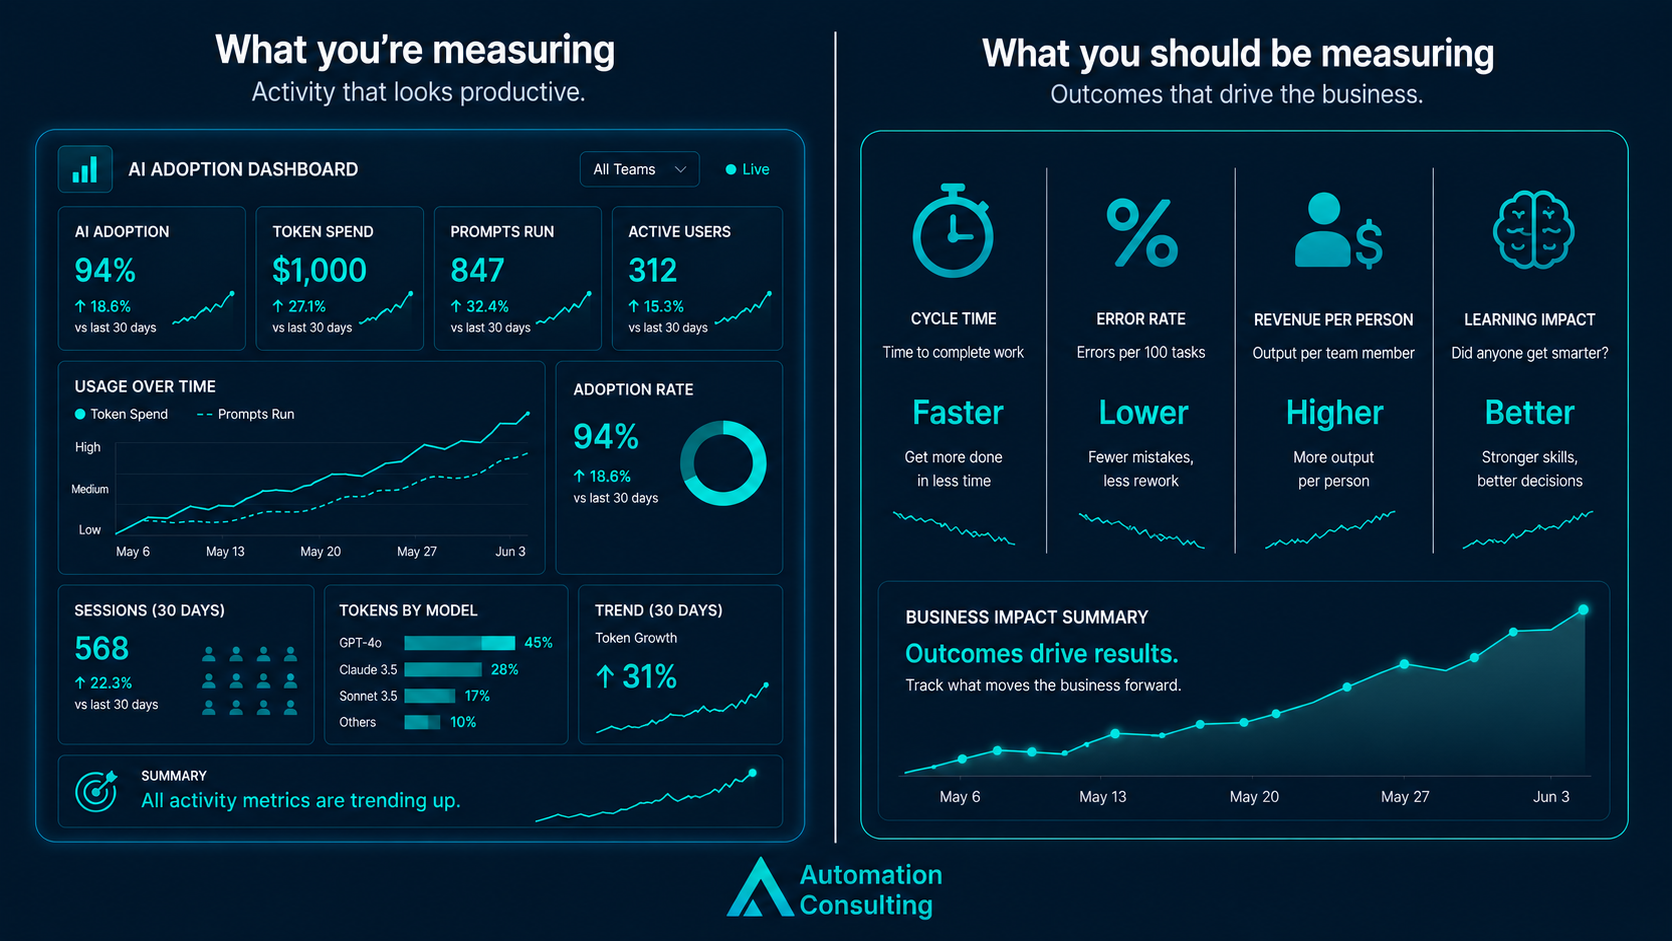
Most companies are in the same position. Their dashboards show adoption climbing, spend growing, prompts running. None of those numbers answer the question that matters: compared to before AI, what actually got better?
The reason is structural. A token-usage dashboard is a school attendance record. It tells you whether students showed up. A school with 98% attendance and no learning outcomes is not a good school — it is a very good roll-call system. Most AI programmes work exactly the same way.
The fix is not a better dashboard. It is running the sequence in the right order.
Uber COO Andrew Macdonald Rapid Response AI Productivity – Automation Consulting
The short version
Token dashboards measure activity, not outcomes. Spend climbing is not value growing.
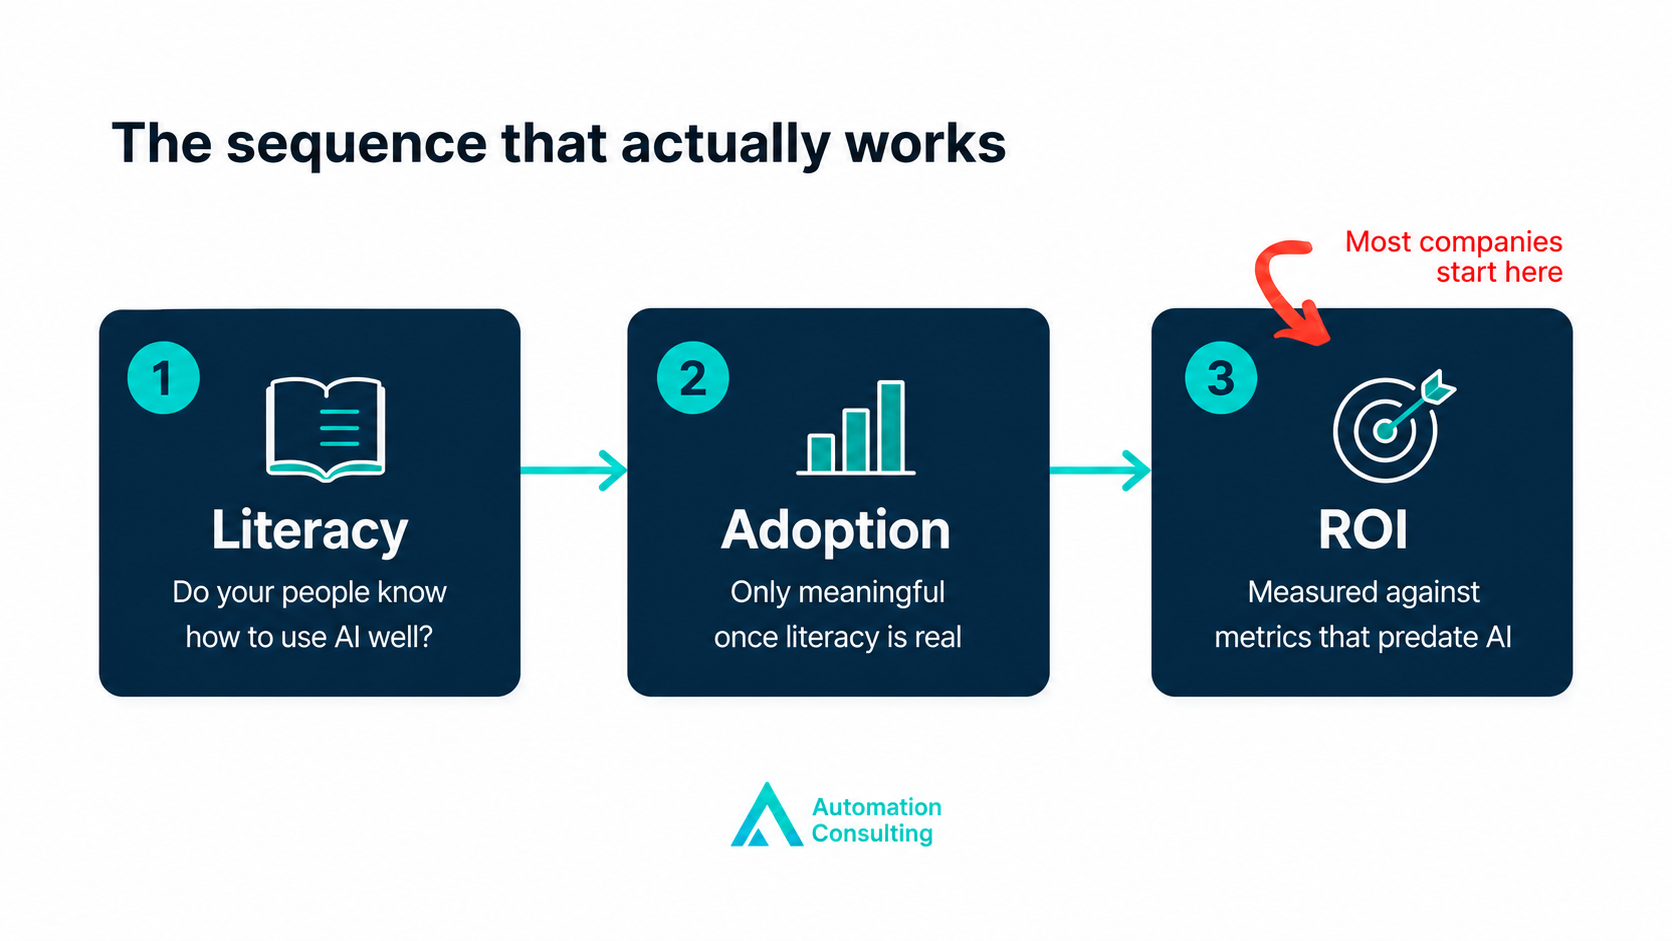
The correct sequence is literacy, then adoption, then ROI — in that order. Most companies have inverted it.
Each step has a concrete test. If you cannot pass the test for step one, step two’s numbers are meaningless.
ROI must be measured against a pre-AI baseline. Not tokens consumed. Not hours saved as self-reported.
A metric that only exists because AI exists cannot tell you whether AI worked.
The $1,000 version
A COO at a company roughly the size of a serious Australian SME set a KPI around AI token usage: spend per engineer. The usual instinct once a number starts climbing and nobody can explain why.
He spent $1,000 in API costs solving two issues. On a dashboard, that looks like adoption working. But look closer. The $1,000 was on top of his own time: prompting, re-prompting, checking, correcting. The task took roughly the same time it would have taken without AI. He used it anyway, because the company needed the metric to move.
The spend was not buying capability or productivity. It was buying attendance records at API prices. The roll-call looked perfect. Nobody asked whether the class had learned anything.
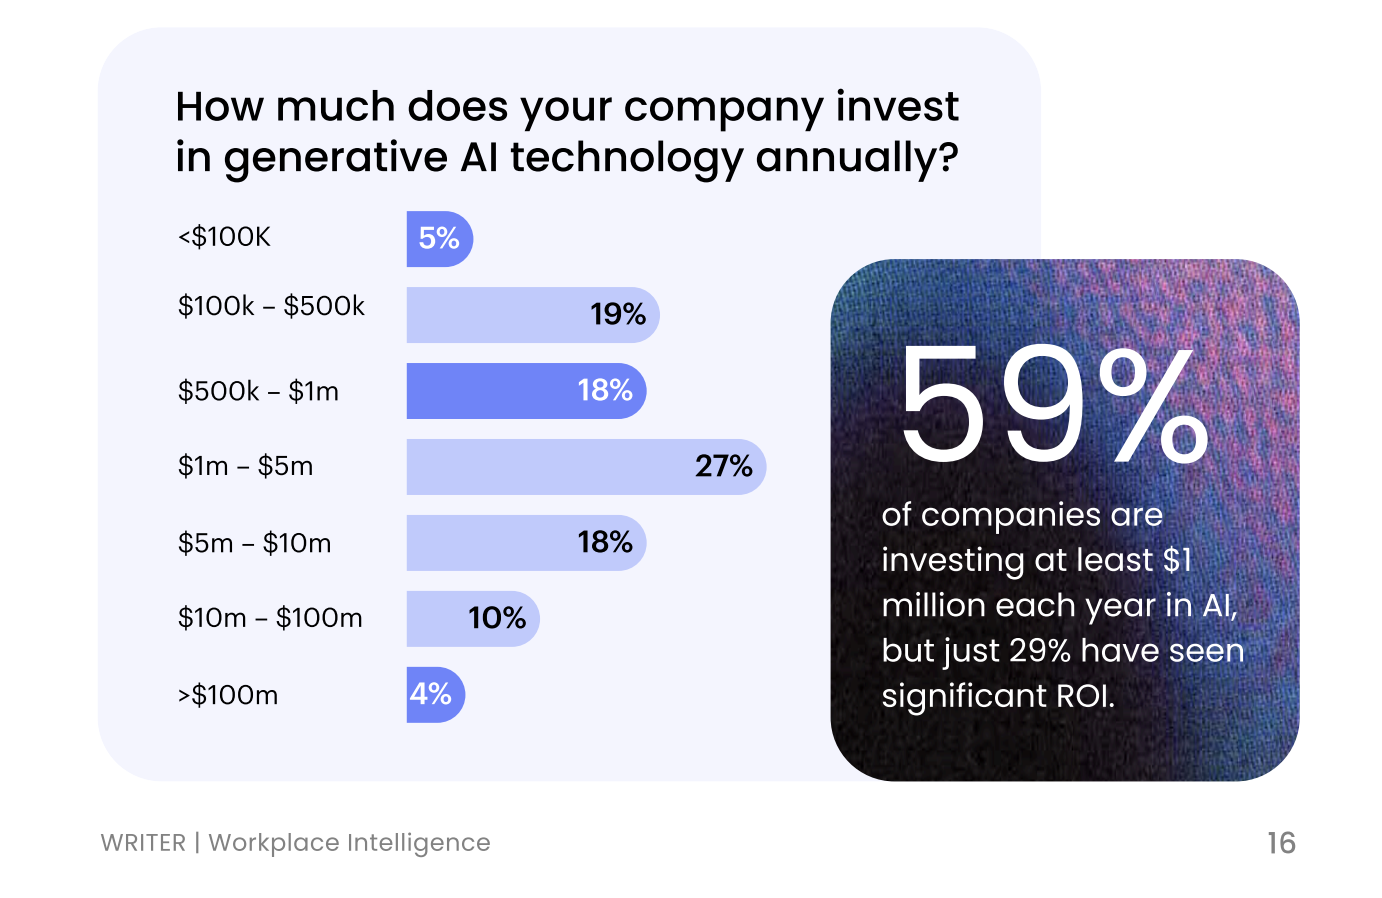
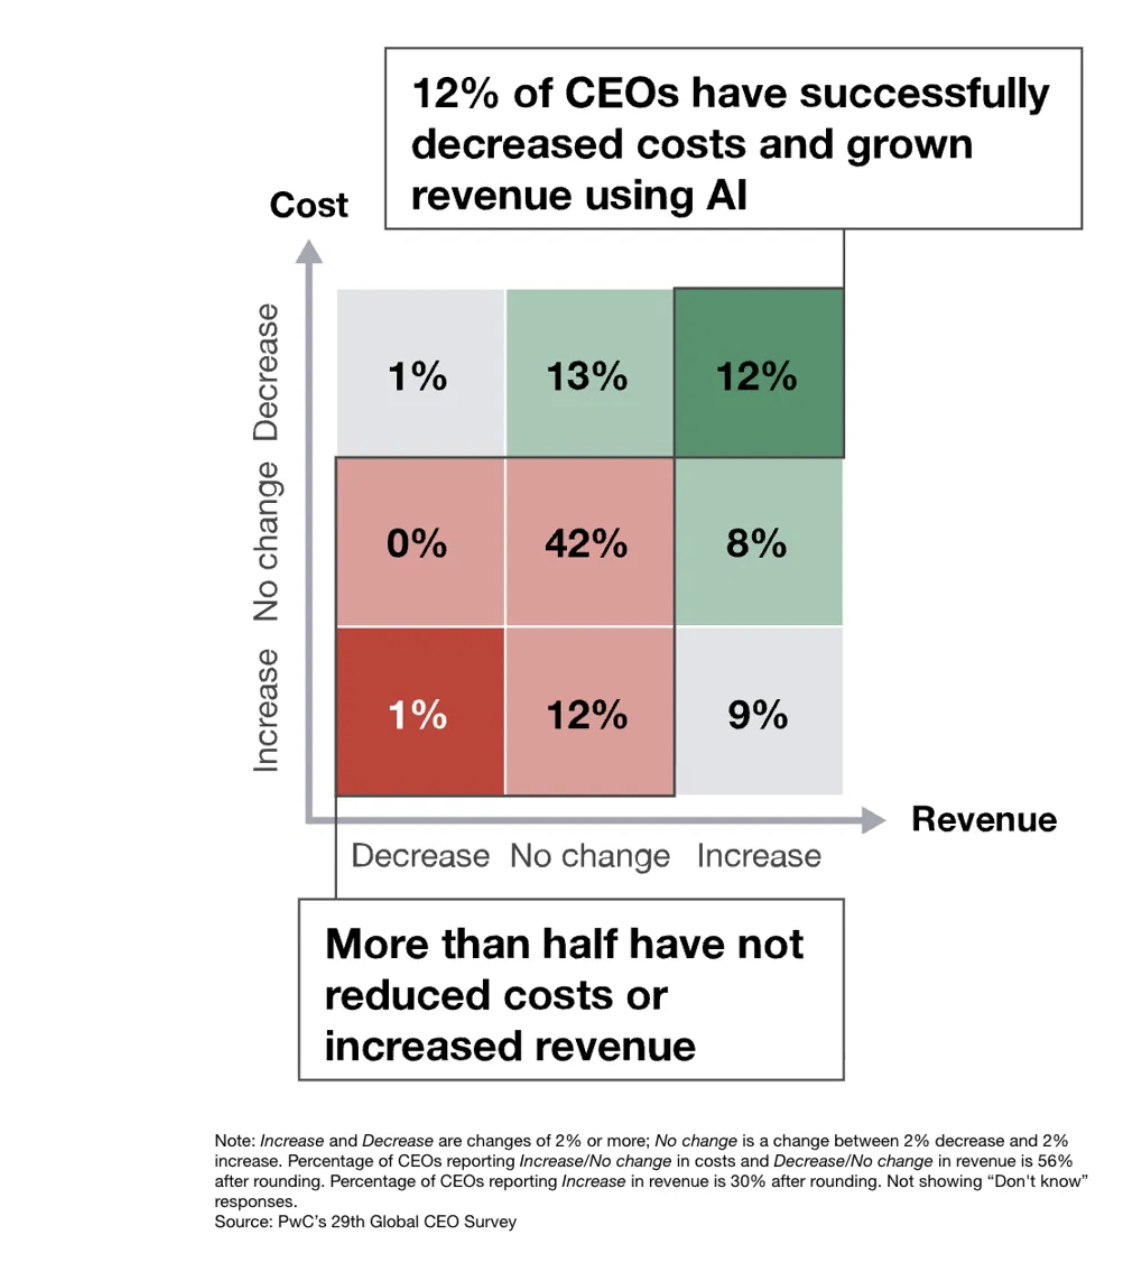
This is not an isolated case. According to Writer’s 2026 Enterprise AI Survey, 59% of enterprises invest at least $1 million a year in AI. Only 29% report significant ROI. PwC’s 29th Global CEO Survey found just 12% of CEOs could identify both reduced costs and grown revenue from AI in the past twelve months.
The gap between spenders and earners is not technology. It is sequence.
Writer Workplace Intelligence AI ROI Survey 2026 – Automation ConsultingPwC 29th Global CEO Survey AI ROI – Automation Consulting
The sequence that actually works
AI ROI Measurement Sequence: Literacy, Adoption, ROI – Automation Consulting
The order matters. Almost no one follows it.
Step 1: Literacy
What it means:
The people using AI know how to use it well. Not whether they use it — whether they use it well. A team that prompts poorly, cannot verify outputs, and does not know when AI is the wrong tool is a spending team, not a capable one.
Why it comes first:
A team with low AI literacy spending confidently looks identical, on a dashboard, to a team with high AI literacy spending confidently. The dashboard cannot tell them apart. This is the same problem software engineers faced a generation ago when they were paid by lines of code written. The engineer who solved a problem in 50 lines got penalised against the one who wrote 500. Precise prompting uses fewer tokens. The dashboard rewards volume. It cannot see quality.
How to test it:
Pick one task your team runs regularly. Run it with AI. Compare output quality and time taken against your pre-AI baseline. Three questions:
Did the AI-assisted output meet the same quality bar as the manual version?
Did it take materially less time, accounting for prompting and verification?
Did the person doing it feel in control of the output, or were they hoping it was right?
If the answer to any of these is no, literacy is the constraint. Do not move to adoption metrics until this passes. A skills session, a prompt library, or a structured review of how the team is actually using the tools will do more than any dashboard.
AI ROI School Attendance Analogy – Automation Consulting
Step 2: Adoption
What it means:
Once literacy is real, adoption tells you how much of the potential is being captured. Before that point, adoption is spend with better attendance records.
Why it comes second:
High adoption across a low-literacy team is a cost problem disguised as a progress metric. You are paying for scale before you have proven the thing scales well. The number goes up. The outcome does not follow.
How to measure it meaningfully:
Adoption only means something when measured against a specific workflow with a known literacy baseline. The question is not “what percentage of the team used AI this week.” The question is “what percentage used AI well on the tasks where we know it should help?” Two things to track once literacy is established:
Workflow coverage: For the tasks where AI has been proven to work, what percentage are being run through it consistently?
Reversion rate: How often do people complete a task with AI and then redo it manually? Reversion is the most honest signal that literacy is not yet there, regardless of what the adoption figure says.
If reversion is above 20% on a given workflow, treat that as a literacy problem, not an adoption problem. More prompting to use the tool is not the fix.
Step 3: ROI
What it means:
A measurable change in a business metric that existed before AI did. Cycle time. Error rate. Revenue per person. Customer response time. Defect rate. Not tokens consumed, not prompts run, not hours saved as self-reported.
Why it comes last:
A metric that only exists because AI exists cannot tell you whether AI worked. The comparison must be to before — which requires having recorded what before looked like.
How to measure it:
Three steps.
Set the baseline first. Before any new AI rollout, record current performance on the workflows you intend to change. This takes an afternoon. Reconstruct from historical data if you missed it: project management tools, email timestamps, invoicing records, support ticket logs.
Run a 30-day comparison. Once AI is operating on the workflow, measure the same metrics over 30 days — not a new set of metrics designed to make the comparison easier. Compare directly.
Be honest about confounding factors. If the team changed their process at the same time as adopting AI, you cannot cleanly attribute the outcome. Note the confounds and account for them.
If the outcome metric improved, you have a case for continued investment. If it did not, the constraint is usually literacy, not the tool. Buying more access before addressing literacy does not fix the problem.
AI ROI: What You’re Measuring vs What You Should Be Measuring – Automation Consulting
This is where most AI automation investments quietly disappoint — not because the tools do not work, but because the measurement framework was wrong before the first prompt was written.
How to measure AI ROI in practice: a 90-day plan
For a business starting from scratch, here is what running the sequence actually looks like.
Days 1 to 30 — Literacy sprint. Pick one team, one workflow. Run the literacy test. Identify gaps. Run one targeted training session or build a shared prompt library for that workflow. Re-run the test. Do not move forward until the team passes it.
Days 31 to 60 — Adoption measurement. With literacy established on that workflow, measure adoption and reversion. Set a target: 80% consistent adoption, under 20% reversion. If you hit it, the workflow is ready for ROI measurement. If not, go back to literacy.
Days 61 to 90 — ROI measurement. Compare the 30-day AI-assisted performance against the pre-AI baseline on your chosen metric. Document the result. Use it as the template for the next workflow.
At 90 days, you have one workflow with a defensible ROI number and a repeatable process for the next one. That is more useful than six months of token dashboards across the whole business. If you want a structured approach to this across your organisation, our technology strategy service is built around exactly this kind of diagnostic.
What Uber’s problem actually was
Uber’s problem was never that the budget grew. Budgets for capable things grow.
The problem is not having an answer, four months in, to the older and far less exciting question: compared to before, what actually got better, and by how much?
Andrew Macdonald’s test was exactly right: how many projects on the cutting room floor got moved forward because AI accelerated the engineering work? The answer, he said, was hard to draw a clean line to — even when token usage was trending astronomically.
Counting tokens spent is not the same as counting problems solved. The dashboard has perfect attendance. It just cannot tell you whether the business got smarter.
AI ROI is the measurable change in business performance attributable to AI adoption, expressed against a baseline that existed before AI was introduced. It is calculated by comparing pre-AI metrics — cycle time, error rate, revenue per person, response time — against the same metrics after AI has been running at scale. Token spend, adoption rates, and hours saved as self-reported are activity metrics, not ROI metrics.
Why can’t I use token usage to measure AI ROI?
Token usage tells you what AI cost, not what the business gained. A team with low AI literacy spending confidently produces the same token dashboard as a high-literacy team. A high-literacy team will often use fewer tokens because they prompt more precisely — meaning they look worse on the dashboard despite performing better. ROI requires an outcome metric with a pre-AI baseline, not a cost metric without one.
What should I measure before rolling out AI?
Before AI adoption, record the baseline performance on the workflows you intend to automate or augment. Relevant metrics depend on the workflow: processing time, error rate, throughput per person, cost per unit, customer response time. Capturing these before adoption is what makes an honest ROI comparison possible later.
What is AI literacy and why does it come before adoption?
AI literacy is the practical capability to use AI tools effectively: knowing how to write a useful prompt, when AI is the wrong tool, and how to verify outputs. It comes before adoption metrics because adoption without literacy produces spend, not capability. A team using AI poorly at scale costs more than a team not using it at all, and both look identical on an adoption dashboard.
How long should I wait before measuring AI ROI?
Enough time for the workflow to stabilise and for the comparison period to be equivalent to your baseline period. For most operational workflows, 30 to 90 days of consistent AI-assisted operation is the minimum for a credible comparison. Measuring at week two, before the team has developed genuine proficiency, produces results that are neither representative nor defensible.
Our AI spend is growing but we can’t explain the value. What should we do?
Pause new adoption and run a diagnostic on one workflow. Reconstruct a pre-AI baseline from historical data. Measure the same workflow with AI over 30 days. If the outcome metric improved, you have a case for continued investment. If it did not, the constraint is likely AI literacy, not tool capability. Buying more access to the tool before addressing literacy does not fix the problem.
Fable 5’s free-access window has been extended to July 19, 11:59:59 PM PT. After that, it’s usage credits at $10/$50 per million tokens, double Opus 4.8. We covered what to build before the deadline here. This post is about making whatever time you’ve got left go further.
None of what follows is “just use it less.” These are six specific, sourced techniques people are actually running, with the real numbers.
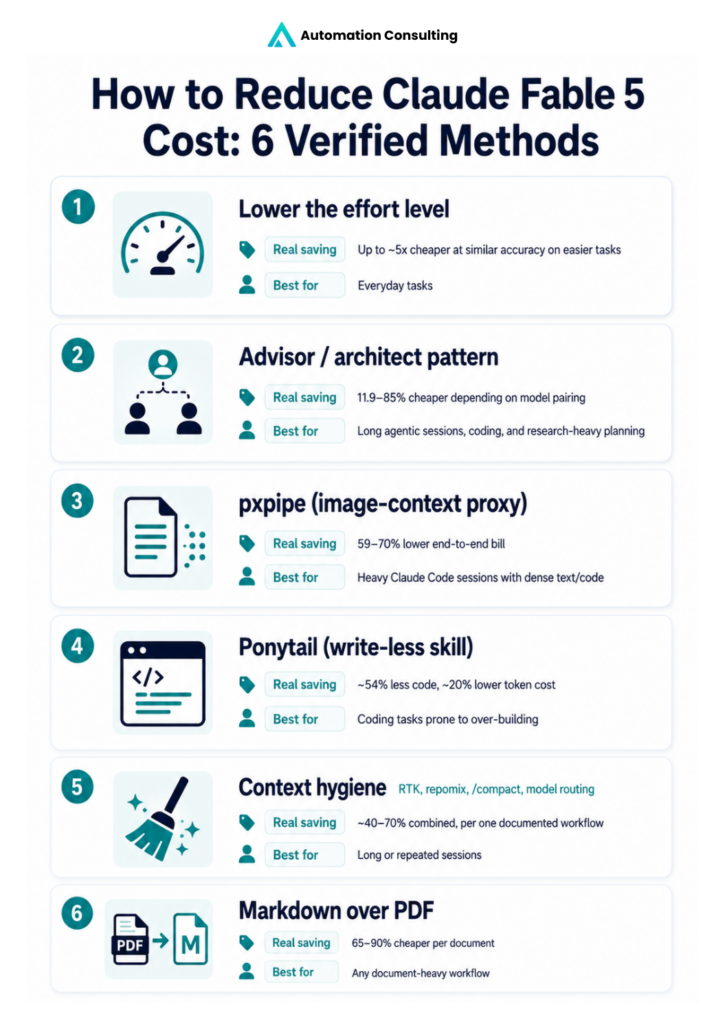
The short version:
Drop the effort level: Most tasks don’t need max effort, the accuracy gap is smaller than the cost gap.
Let Fable plan, let a cheaper model execute (and vice versa for research): Anthropic’s own advisor tool cuts cost 11.9–85% depending on the pairing; for anything needing current information, have a cheaper model research first via /deep-research, then hand the findings to Fable to plan.
Try pxpipe: a free proxy that renders your background context (not your live message) as images, ~59–70% lower bills, but lossy for exact strings buried in that history.
Add Ponytail: a “write less code” skill, ~54% less code and ~20% lower token cost, independently corrected down from an inflated first claim.
Clean up your inputs: compress noisy output, route by model, /compact often; one developer cut usage ~40–70% doing this alone.
Fix your file formats: Markdown over PDF saves 65–90%; crop screenshots instead of uploading them full-size.
Method
Real saving
Best for
Watch out for
Lower the effort level
Up to ~5x cheaper at similar accuracy on easier tasks
Everyday tasks, not genuinely hard problems
Real accuracy drop on the hardest tasks
Advisor / architect pattern
11.9–85% cheaper depending on model pairing
Long agentic sessions, coding, and research-heavy planning
Only helps if the cheaper model can genuinely handle its half of the split
pxpipe (image-context proxy)
59–70% lower end-to-end bill
Heavy Claude Code sessions with dense text/code
Lossy on exact IDs, hashes, long numbers
Ponytail (write-less skill)
~54% less code, ~20% lower token cost
Coding tasks prone to over-building
Gains near zero on already-minimal code
Context hygiene (RTK, repomix, /compact, model routing)
~40–70% combined, per one documented workflow
Anyone running long or repeated sessions
Takes setup time upfront
Markdown over PDF
65–90% cheaper per document
Any document-heavy workflow
Complex visual layouts can lose fidelity in conversion
1. Drop the effort level. Seriously!
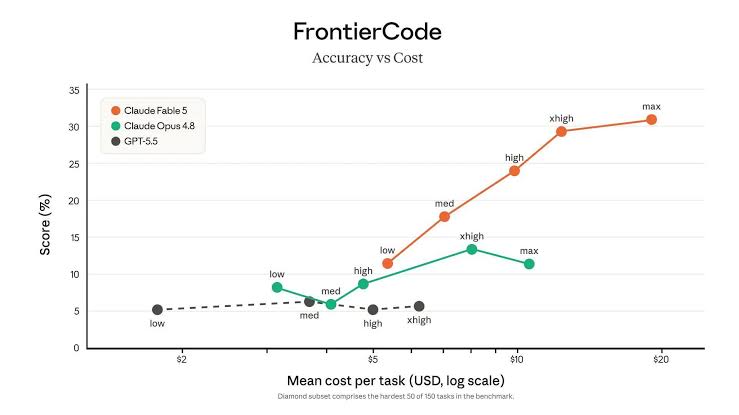
By default, Fable 5 runs on a fairly high effort setting, and most people never touch it. Anthropic’s own benchmark data shows why that’s expensive: on FrontierCode Diamond, accuracy climbs from about 11.5% at low effort to roughly 30.9% at extra-high – real gains, but not gains that every task needs. On SWE-bench Pro, the spread is smaller: 75.0% at low effort versus 80.4% at extra-high.
That means: if your task isn’t genuinely hard — a web tweak, a straightforward edit, a routine question — running it on max effort is paying architect rates for a job that doesn’t need one. Drop to medium or low with /effort and see how the output holds up first.
2. Make Fable the architect, not the typist
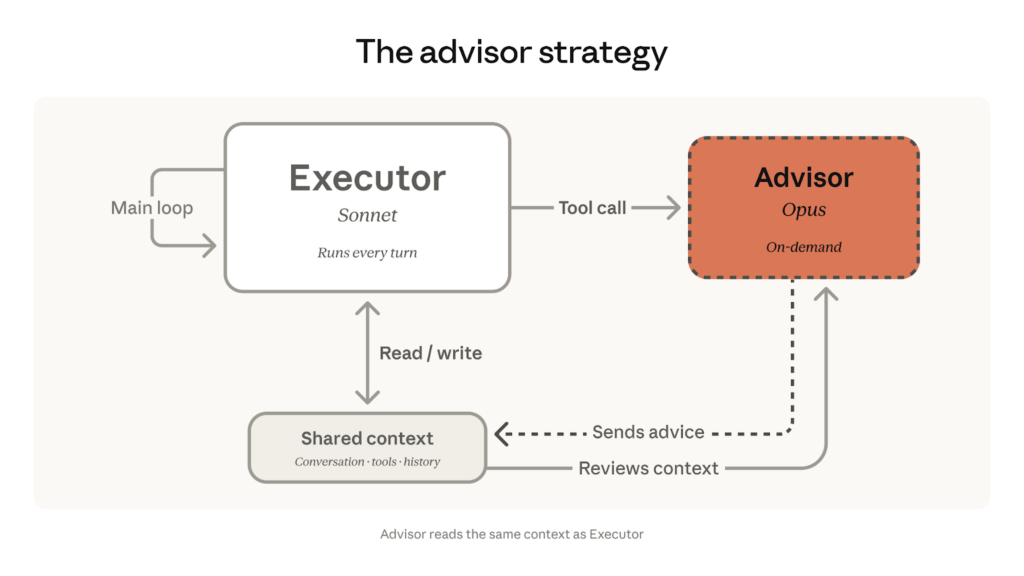
Anthropic has an actual feature for this: the advisor tool. Instead of running Fable 5 for an entire session, you let a cheaper model (Sonnet or Haiku) execute the task end-to-end, and only escalate to a stronger model when it hits something it can’t resolve alone.
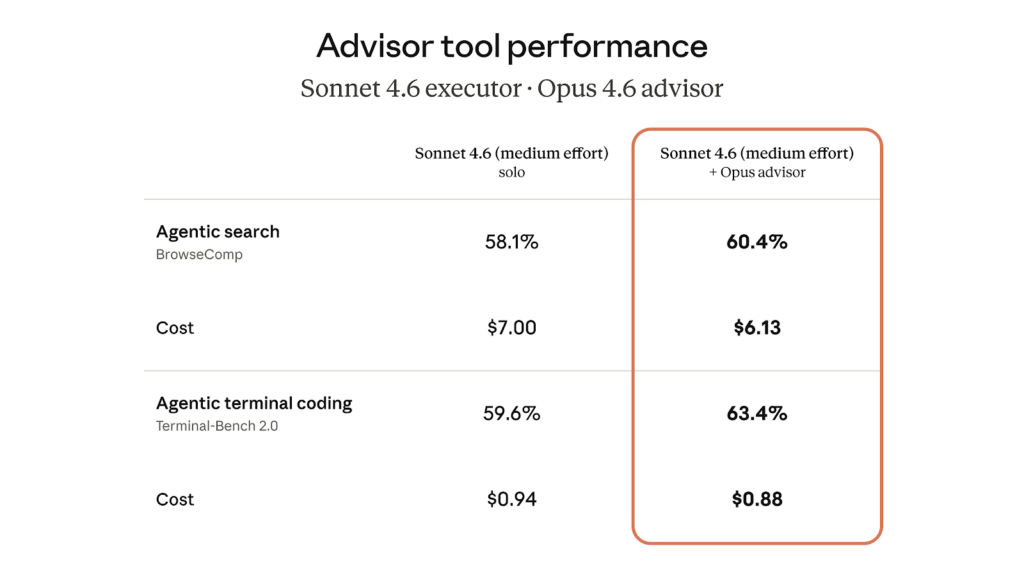
The published numbers are real and specific: Sonnet with an Opus advisor cost 11.9% less than running Opus solo while scoring slightly higher on SWE-bench Multilingual.
Claude Advisor Strategy – Sonnet versus Sonnet + Opus
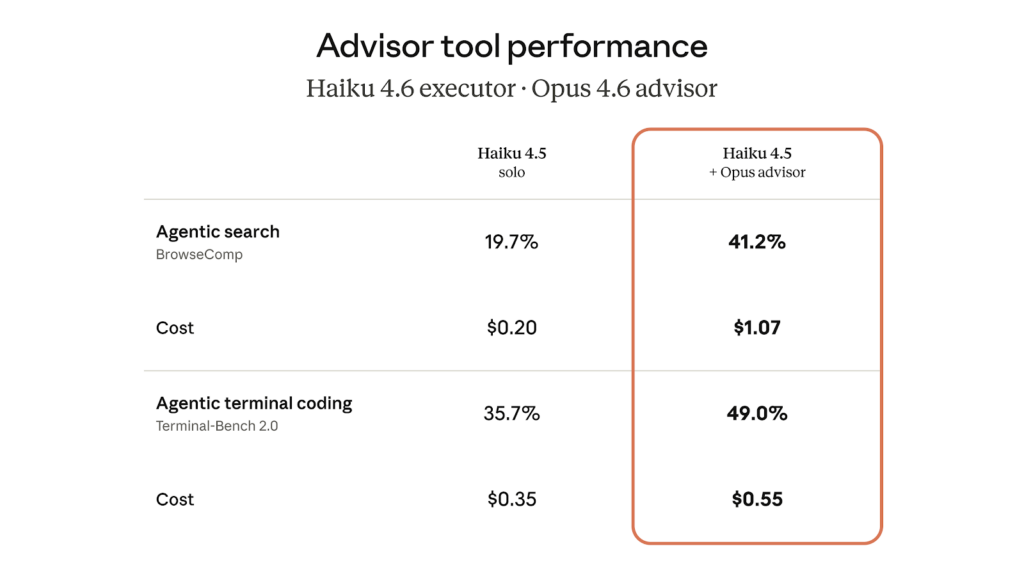
Haiku with an Opus advisor cost 85% less than running Sonnet alone, while roughly doubling Haiku’s score on a hard benchmark.
Claude Advisor Strategy – Haiku versus Haiku + Opus
In Claude Code, this is /advisor — or the related /model opus-plan, which runs planning on the stronger model and execution on the cheaper one automatically. The same logic applies to Fable 5: let it plan and make the hard calls, hand the actual typing to Sonnet.
The reverse pattern works tooFable 5’s knowledge cutoff isn’t yesterday, so if a plan needs current information — recent docs, a changelog, competitor pages — that’s not a job that needs Fable-level reasoning, it just needs someone to go and look. Claude Code’s built-in /deep-research workflow fans out web searches across a cheaper model, cross-checks the sources against each other, and hands back one cited report — which you then feed to Fable 5 to actually plan against. Cheap model gathers the facts, expensive model reasons over them. Running that same fan-out research on Fable 5 itself would blow through your usage cap for a step that doesn’t need its reasoning at all.
3. Try pxpipe — turn your context into pictures
This one sounds like a joke and isn’t. pxpipe is a free, open-source local proxy that intercepts requests to Claude Code and converts the bulky, repetitive parts — your system prompt, tool documentation, older conversation history — into PNG images before they’re sent to the model. Claude reads the image back with its vision capability instead of reading it as text.
pxpipe demo – How to Reduce Claude Fable 5 Cost – Automation Consulting
What it doesn’t touch matters as much as what it does. Your actual current message and everything the model outputs stay as plain text throughout — pxpipe only targets the static, repetitive background context that gets re-sent unchanged on every turn. That distinction is the whole reason this is usable in practice: the parts where getting the answer exactly right matters most (your live question, its live response) are never run through the lossy part at all.
The reason it works: Anthropic prices images by pixel dimensions, not by how much text is packed inside them. Dense content like code or JSON can fit roughly 3 characters per image-token, versus about 1 character per text-token. The developer’s own published numbers: a real session that cost $42.21 running as plain text cost $6.06 through pxpipe — a genuine, documented 59–70% reduction on production workloads.
Two lines to try it:
npx pxpipe-proxy
ANTHROPIC_BASE_URL=http://127.0.0.1:47821 claude
4. Add a “write less” skill
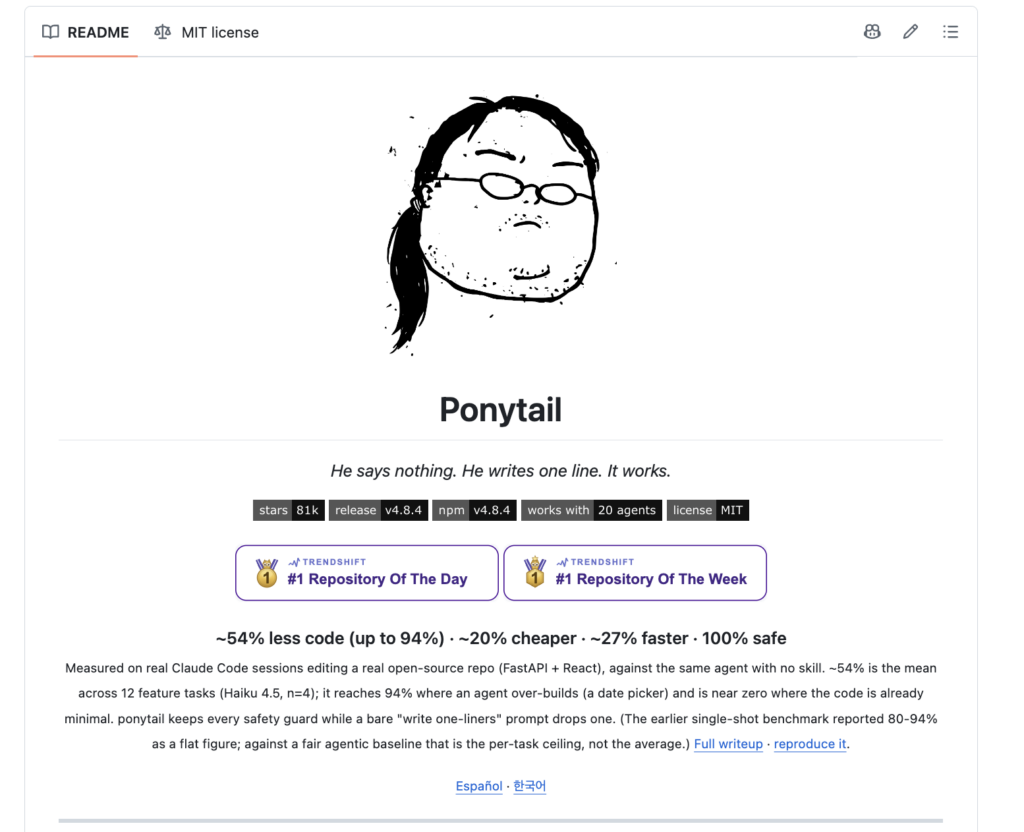
Ponytail is a free Claude Code skill built around one idea: install a “lazy senior developer” mindset that asks, before writing anything, “does this need to exist at all?” It stops agents from over-building — reaching for a library and a wrapper component when a native browser feature would do.
Ponytail – How to Reduce Claude Fable 5 Cost – Automation Consulting
Worth knowing the full story here, because it’s a good lesson in checking numbers rather than trusting a headline: Ponytail’s first published benchmark claimed 80–94% less code. A user pointed out the comparison was unfair — the baseline being compared against wasn’t given the same instructions, so part of the gap was an artifact of that mismatch. The author accepted the criticism and re-ran it properly. The corrected, defensible number: about 54% less code on average, with roughly 20% lower token cost and 27% faster runs, tested on a real FastAPI/React repository, with zero drop in security or error-handling scores. Independent testing on Opus found even better results than the original Haiku-based benchmark.
That’s a more honest number than the first version, and it’s still a real saving. Install it in Claude Code:
/plugin install ponytail@ponytail
5. Clean up what you feed it before you feed it (the save-tokens-in-Claude-Code stack)
This is the boring one and probably the highest-leverage one. A developer running a heavy Claude Code workload every day documented the stack that got him a 60–70% reduction versus running everything raw:
Compress noisy CLI output before it reaches Claude: A tool like RTK dedupes repeated lines from grep or git diff output — real numbers cited: 76% efficiency on one session.
Ship a curated project snapshot, not the whole repo: Tools like repomix (23k GitHub stars) or code2prompt (7k stars) strip lockfiles, build output, and generated code before Claude ever sees the project.
Route by task, not by habit: Save the expensive model for planning and genuinely hard problems; let Sonnet handle file-by-file edits. One developer reported this alone cut weekly usage by roughly 40% with no quality drop he could feel.
/compact aggressively, or just start a new session: Long conversations get re-read in full on every turn — token cost grows close to quadratically the longer a session runs.
Write terse prompts for trivial stuff: The so-called “caveman” style — dropping pleasantries and background context for quick lookups — trades some nuance for a real cut in input tokens. Save full sentences for anything touching production.
6. Format is a cost decision, not just a preference
This one’s about what you feed it, not how you run it.
Markdown beats PDF, and it’s not close. A PDF page can cost Claude roughly 1,500–3,000 tokens, because it’s not just reading your content — it’s processing embedded fonts, layout instructions, and rendering noise you never see. The same content saved or converted as plain Markdown can cut that by 65–90%. If you’re regularly uploading reports, contracts, or proposals as PDFs, converting them first (Microsoft’s free, open-source markitdown tool does this in one step) is one of the cheapest wins available.
If you are working with screenshots, crop them. A 1000×1000px image costs roughly 1,334 tokens; a cropped 200×200px region of the same image, showing only what matters, costs about 54 tokens — a 25x difference for the same useful information.
What we’d skip
Not every “hack” making the rounds is worth your time:
Custom tokeniser tricks: Fragile, save pennies, break with the next model update.
Prompt-shortening middleware “agents.”: Often add latency and make output worse, not better.
Switching providers mid-task to save a few cents: The context you lose costs more than what you saved.
A word on timing
Anthropic themselves have said this exploit-the-pricing-gap approach (pxpipe specifically) is unlikely to stay open indefinitely — if enough people lean on it, expect the underlying pricing to move. Treat the specific tricks in this post as a current window, not a permanent floor. The habits — right-sized effort, right model for the job, clean context — are durable regardless of what Anthropic changes next.
6 Verified Methods to Reduce Claude Fable 5 Cost – Automation Consulting
Common questions
1. What is Claude Fable 5’s pricing after the free window?
$10 per million input tokens and $50 per million output tokens — double Claude Opus 4.8’s rate. That’s the highest published rate for any generally available Claude model, which is exactly why the methods in this post matter more once the Claude Fable 5 usage limit resets to standard billing.
2. Do these tricks work on Opus 4.8 and Sonnet 5 too?
Yes, mostly. The advisor pattern, context-cleanup habits, and Ponytail all work across models. pxpipe currently defaults to Fable 5 and GPT-5.6 specifically, though it can be configured for others.
3. Is pxpipe safe to use with sensitive data?
It runs entirely locally before anything reaches Anthropic’s servers, but because it’s lossy for exact strings, avoid using it on anything where a subtly wrong ID or hash would cause a real problem — keep those in plain text.